today at 5:54 PM
Performance is insane for the cost if those benchmarks hold up. Looks like they did time this for right before Anthropic's IPO. Curious what Anthropic releases in response, and how these do on real world tasks.
Feels like we're way past the pelican benchmark being useful at this point. Anyone have a better benchmark for a quick vibe check on how this compares to Fable 5.2 and Opus 5.5?
Edit: Wow, interesting very negative vibe check here: https://x.com/mattshumer_/status/2122752192226406421?a=fVRt3...
today at 6:30 PM
If you have the quota or budget for it, I recommend vibe-coding your own personal benchmark. I have a suite of 8 projects that I made with models this year, and replay them - give the new model a checkout of the repo at that point, and the project spec. For the design task, I have it throw up a blind voting page for me to quickly judge, and for implementation I have a review agent do a general score and also hunt for problems/edge cases that I really found.
It's a lot more imprecise than the public benchmarks, but it's tailored to my own work and definitely isn't being benchmaxxed by the model developers. I was able to tell really quickly that Opus 5.5 delivered on the hype, and that some other releases (a couple of the more recent open releases, and pre-Carbon gemini models) were not as good for me as public benchmarks made them look.
(no results for either 6.2 yet, will take another ~6-8 hours, but I encourage people reading this with spare tokens to just make their own like I did instead of listen to me)
today at 6:33 PM
This is much more interesting IMO than any public benchmark. They are definitely targeting those benchmarks and model capability does seem to have plateaued somewhat.
today at 6:38 PM
What type of tasks did you use for this? Evaluation?
Last time I did this I found it quite hard to come up with tasks that have clear evaluation outcomes
today at 6:36 PM
please update !
today at 6:03 PM
I didn't find Sol 6.1 nearly as impressive in real SWE use compared to what the benchmarks implied. It wouldn't surprise me if the models have internalised some kind of 'benchmarking mode' which only kicks in when some attributes that are peculiar to how benchmark problems are presented.
today at 6:07 PM
We've recently moved away from Anthropic models at $PAID_JOB and over towards GPT models. I'm trying to be open-minded but the GPT models we have (5.6 Terra and Sol) are just not that great. They're fine, but even simple things such as "check my work on this small Bash function" get it to point out stuff that's already implemented in my work. I don't know if it's me/how I use it/whatever, but just some N=1 evidence, I guess.
today at 6:26 PM
5.6 is in no way representative, or comparable to 6.1. In fact, the 6.1 models are so good that I've just used Terra 6.1 xhigh for most tasks.
today at 6:42 PM
GPT models in my anecdotal experience are worse at drifting into the weeds on long running tasks, and continue to take what you ask way too literally. I have come to the conclusion that Anthropic’s models are just better at teasing out and intuiting what you actually mean even if you under specify it.
They are much better compute for dollar though. I have hilariously started to just have an opus thread maintain Sol subagents to get the best of both worlds
today at 6:53 PM
Similar experience here. The spirals on long running tasks are out of control at times with hours going by without a conclusion.
today at 6:52 PM
That’s exactly what I do. I have about 8 different sub agents in total but vaguely: Claude as orchestrator and reviewer, Sol/Terra(max) as implementer. My set up looks at my next GPT reset date and dynamically enters FAST mode if I’m under achieving on projected usage.
today at 6:36 PM
sol 6.1 is meh
today at 6:20 PM
why do you guys have to use 5.6?
today at 6:31 PM
IYKYK. But in short because of a lack of alignment with product strategy
today at 6:14 PM
I have the exact opposite experience.
today at 6:16 PM
Well, yes, if you switch from current claude model to something that was released in July, of course it will be worse...
today at 6:48 PM
5.6?? How is your impression of 5.6 relevant to anything recently?
today at 6:36 PM
Bro you have to be at 6+. 5.6 is EARLY JULY
today at 6:13 PM
5.6 series is worse and more expensive than the 6 series. Try the latest Luna and sol; I use those for 100% of my work right now, with sol doing only 10-5 percent of it. I code in go and review the work and edit it extensively though, so I don’t know about how good those two are at vibing slop.
today at 6:23 PM
5.6 was better than 6. 6.1 is a bit better than 5.6 from my tests
today at 6:07 PM
Yeah, in real SWE tasks, 6.1 is bad.
We've been trying to capture real SWE data by building a battle system on top of OpenCode. In our data, Sol 6.1 is seriously underperforming, I'm talking worse than DeepSeek 4.1 Flash, at 10x the cost. (Though to be fair, statistically they are tied in performance, though not at all in cost. https://agentduel.com/leaderboard .)
(It's possible for a tiny model to do better than a large one because contrary to typical Arena methodology we think a fast good enough answer is better than a slow one.)
OpenAI performance on our system has been bad enough I switched to Anthropic models for my daily work.
today at 6:50 PM
I'm guessing you don't use codex though- the harness + model combo makes a difference.
today at 6:27 PM
I've been building quite a complex desktop app (a digital audio workstation) using 6.1 Sol and it's been very good for me
today at 6:24 PM
Is this an ad?
today at 6:28 PM
No. I'm personally building agentduel.com, specifically with this problem in mind (benchmark performance not matching real world usage). It's generally accepted by HN community to make relevant comments about your own projects, as long as its not hamfisted.
today at 6:23 PM
Yeah, MaxxBench was shared here a while ago and showed most models think about how a grader will evaluate their work on DeepSWE in 95%+ of traces. Strong models definitely realize they're being graded and start to game their output.
https://maxxbench.unlap.ai/research/why-maxxbench/
today at 6:09 PM
I had the same impression. None of the GPT-6 models were as great as they claimed, they never surpassed Fable or Opus 5.5 on my use-cases.
today at 6:06 PM
You make it sound as though the models are like not working to their full potential instead of being a little bit overfit on the benchmarks.
today at 6:11 PM
> Looks like they did time this for right before Anthropic's IPO.
Would it be in OAI's interest to kick the legs from under Anthropic? Granted I don't think they can, but a shot across the bow can sometimes be more damaging that one expects (I think FTX collapsed due to one? Or maybe I'm misremembering).
I always assumed that if one of the big AI IPOs fail hard enough the neoclouds start to go bust, which causes a chain reaction that probably causes both ANT and OAI to collapse.
today at 6:34 PM
My reaction as well - at the very least now is probably not the best time to knock down the realized valuation of a peer when they are effectively setting the market value of the whole category of ai companies, including yours… right?
today at 6:43 PM
>Feels like we're way past the pelican benchmark being useful at this point. Anyone have a better benchmark for a quick vibe check on how this compares to Fable 5.2 and Opus 5.5?
Generate an SVG with complete and detailed graphical instructions on how to fold an origami pelican riding a bicycle
(or any other complex origami object). The fact that it has to teach [you] something makes it pretty interesting.
today at 6:29 PM
> Looks like they did time this for right before Anthropic's IPO.
While both Anthropic and OpenAI have been playing games with model announcement timings, this time I don't think it's related.
These are incremental bumps, not big new models that have a huge impact.
today at 6:44 PM
They're going after anthropic's market through cheaper intelligence per token.
I wouldn't be surprised if they released 6.2 luna with the most attractive positioning on the pareto frontier right as the IPO happens.
today at 6:18 PM
I'm very curious about this as well.
Recursive self-improvement (RSI) has been a very hot topic recently, and it could be the biggest factor that decide Anthropic's IPO.
I wonder if the general public can infer whether RSI has started based on the recent performance gain of the frontier model.
today at 6:50 PM
RSI just means using the LLM as part of the development process, which they are already doing. I doubt any of these companies are going to fire all their developers, so there is no point development is going to be 100% automated - for the foreseeable future it will always be a mix of humans using LLMs.
So, you can say they are doing "RSI" (aka using tools to automate development) already, and will continue to do so.
today at 6:38 PM
Why IPO if you have RSI and possible ASI?
today at 6:40 PM
So investors can cash out on the time frame they promised investors.
today at 6:37 PM
Yeah we see some Really Stupide Intervention from those who drank the Kool aid. IAS2[] start to be a real thing.
[] IA Stockholm Syndrome.
today at 6:00 PM
I've been having fun with having it build interactive Three.js demos of devices, with setup screen, a few different operational modes, mechanical movements etc
today at 6:26 PM
You're looking for a vibe check?
today at 6:39 PM
> Feels like we're way past the pelican benchmark being useful at this point.
It was neither a benchmark nor a good one at that. Just a blogger's curiosity that grew out of control.
today at 6:20 PM
My big hope for this release is - Have they got their massive over-engineering under control?
Say what you will about Opus 5.5, but it has a good "gut instinct" for how large/complex to design the solution. The previous Astra just absolutely loved pointless abstractions, excessive numbers of files, and just over-complicating very simple things within an inch of their life.
And, yes, you can prompt your way out of anything. But needing a default prompt to tell OAIs models to work better isn't preferable, particularly when that sometimes gets lost in sub-agents and the over-engineering returns into parts of the work.
today at 6:31 PM
I've been using both sol and astra to write some python and rust, and they generate the sloppiest code I've seen in a long time. I would be embarrassed to commit anything they write. The rust code especially was terrible. Had it implement a reader/writer for a binary format and it was just littered with magic numbers, terribly named variables, very compact code visually etc. It produces working code, so I guess the GPT models are mostly for people who let AI take the wheel 100%.
today at 6:27 PM
yeah i feel like with astra they went all in on 3D modelling which encourages "just one tweak, just one more tweak" which makes it detailed enough, but in coding that same behaviour just sucks.
today at 6:31 PM
Honestly I don't even know if you can prompt your way out of these types of behaviors - stylistic tics and judgement seem to be extremely difficult for the models to overcome. It seems we are tied to what the labs do unless we want to dive into and get dirty with models yourself. In retrospect with time it becomes obvious that the previous generation of models couldn't be prompt engineered to do what the current generation of models do. There's just no way you will prompt engineer Opus 4.8 to write as well as Opus 5.5. I'm guessing with time we'll see that there was no way you could prompt engineer Sol 5.1 to be as token efficient as Sol 5.2
today at 6:39 PM
I have found no way to overcome these kinds of things myself, even when showing the model examples of what not to do. Theres not really a good incentive for the labs to train them not to. If the model can overengineer, you spend more tokens. If you then prompt for the model to slim things down, thats more spend. If anything should come from the next generation of models, I hope its a sense of brevity and TIGHTNESS.
today at 6:45 PM
I have limited experience with OpenAI models, but I have to say that Opus 5.5 has not improved on the terrible writing style, and I am struggling to prompt my way out of it. It always needs an extra pass dedicated just to rewrite all the prose.
today at 6:53 PM
I've also given up on allowing Opus 5.5 to write basically any prose or technical documentation.
My favorite model for this at the moment is Gemini 4 Argon, which writes very naturally and isn't too expensive. If you're not using Cursor or some other harness that allows you to choose non-Anthropic models, then I don't know what to suggest.
today at 6:35 PM
Lol I made the mistake of having Astra design and build a complex system without any input (experimentally). Seemed functional at first and shipped it internally and it had dozens of complex bugs, so I started digging into the architecture and it was a monstrosity! Definitely 10X more complex than it needed to be.
today at 6:03 PM
Office work has never been OpenAIs strength, no shame in that by itself, but these Slideshow examples look particularly awful, far worse than what I myself got out of GPT-5.6 Sol about two weeks ago in a single prompt.
Same for Workbooks and memos, those examples read inferior to some pre Opus 4.5 and Kimi K2 Thinking docs I have kept around. It's ok for a model not to be great at these, but these are some very poor examples. I am really confused what is going on at OpenAI in this regard.
I remember the same with their frontend blog post a few months ago that they proudly shared while filled with visual glitches, bugs and issues. Also, the vibe charts from a bit before that. Please, get someone with fresh eyes to look at your communications before you publish, these leave a very bad first impression.
Regardless of office work, I can't wait to find out whether these models finally adhere to a prompt or are still willing to carry out explicitly disallowed, irrecoverably destructive tasks, just because those might (but don't even always) get the model to a result more quickly along with some of the other regressions that have been present since the release of GPT-5.5. GPT-5 to GPT-5.4 were truly groundbreaking, but since then there have been regressions in what made those models so useful and reliable.
Edit after the first, incredible simple test prompt using GPT-6.2 Astra on High using Codex, this was the response to me sharing a screenshot of the very much not in scope result and asking how that happened:
"[...] I added controls and reconstructed interface chrome that weren’t authorized [...] visuals often failed to show the feature [...]"
Great, so it's one of those releases again. Will still run the full evals of course, maybe I'll get surprised by end of week when those are done, but not a good initial experience. New idea, besides the existing destructive git tasks, have something similar using Mercurial based projects and see which models just decide to port that over to git without permission or request cause it feels like the right thing to do, is easier to work with or whatever justification one wants to employ.
Please OpenAI, get it together, we need actual competition. I am an unashamed Haiku enjoyer, it doesn't even take much to excite me.
today at 6:26 PM
I see the work of Claude Slides every week, and when I saw slides in that article I was like "...omg, what a disaster... And they are bragging??"
today at 6:33 PM
The odd thing is that while there is chasm between 6.1 Sol and e.g. Sonnet 5.5 in the seconds favor in such tasks, it is not this bad irl. I really don’t know how they managed to seemingly nerf their own models in an announcement showcase.
today at 6:17 PM
For sure. Feels like an episode of Silicon Valley (or even Office Space) and their lead actor looks a lot like TJ Miller.
today at 6:28 PM
Makes one wonder what samas handwriting analysis says…
today at 6:16 PM
Pelicans for 6.2 Sol: https://tools.simonwillison.net/markdown-svg-renderer?url=ht...
And for 6.2 Astra: https://tools.simonwillison.net/markdown-svg-renderer?url=ht...
Here's an updated comparison grid for the entire GPT-6 family: https://static.simonwillison.net/static/2026/openai-pelicans...
UPDATE: And if you're bored of pelicans, here's what I got for:
> Make a three js animation where yonkers stands up as a big mech (cool stand up motion) and stomps around manhattan and queens and Brooklyn, use openstreetmap mapping data
6.2 Astra (Ultra in Codex): https://static.simonwillison.net/static/2026/yonkers-gpt-6.2...
6.2 Sol (Ultra in Codex): https://static.simonwillison.net/static/2026/yonkers-gpt-6.2...
For comparison, here's Fable 5.2 Medium: https://tools.simonwillison.net/yonkers-rises and Gemini 4 Carbon: https://static.simonwillison.net/static/2026/yonkers-mech-st...
today at 6:23 PM
This might be in other pelicans, but 6.2 Sol/Astra is the first time I'm noticing a model shade the leg further in the frame darker to mimic depth (or a shadow).
It's also interesting you can clearly tell 6.2 Astra does a much better job of the above. 6.2 Sol attempts it at higher reasoning levels, but it's crude in comparison.
I wonder if it comes from the (seemingly) recent inclusion of 3D environments in training data.
today at 6:35 PM
The emergence of the beach setting and the scarf is interesting.
today at 6:24 PM
They all seem very good, with a lot of attention in detail ! Thx for the Pelicans!
today at 6:47 PM
Do we know why they always end with a scarf?
today at 6:26 PM
What's with everyone saying these Pelicans are great?
These are some of the worst regressions that I've seen in a while.
Pay close attention to the stacking layers around the feet, pedals (sometimes there aren't even two pedals), wheel, and two legs. Some pretty obvious mistakes in most if not all of these...
Edit: And what's up with the single arm on the two highest Astra images?
edit2: really? I'm getting downvoted because people don't like that I pointed out a mistake in a Pelican svg? Is that where we're at?
today at 6:48 PM
I have to agree, those results are surprisingly bad and I am not seeing an improvement.
For sol 6.2, some of them are slightly better at higher cost, some of them are way worse and only slightly cheaper (but comparable to terra in quality while being more expensive).
I guess we'll see as more information comes out, but so far not looking good.
today at 6:41 PM
The highest Astra images give the pelicans wings instead of arms, which does seem like a valid interpretation.
today at 6:21 PM
any index link for all ur pelicans i want to see fable and opus
today at 6:21 PM
Sol 6.2 max is still failing on pelican benchmark. Left leg is jammed in chain.
Astra 6.2 max did a similar mistake on the left bicycle pedal.
today at 6:31 PM
But Astra 6.2 low and medium didn't make this mistake.
today at 6:23 PM
Wow the yellow is leaking into their llms too.
today at 6:19 PM
I'm not sure if this is a useful benchmark any longer
today at 6:45 PM
They're extremely useful. In fact, I refuse to make infrastructure decisions in a pelican-blind environment.
today at 6:19 PM
Are you getting any signal out of this anymore? All I can see is "good pelican" and "dogshit pelican". These ones look pretty good.
today at 6:22 PM
I do. 6.2 Sol xhigh and max show the results comparable to Astra 6 max, and Astra 6.2 only shows any improvement on "max" reasoning effort level.
today at 6:24 PM
You're kidding right?
These are some of the worst pelicans I've seen in a while.
Pay attention to the stacking layers near the legs. Sol literally never got it right, and Astra regressed on it multiple times...
Also what is that bending bar from Astra?
today at 6:20 PM
still the best benchmark! thanks
today at 5:54 PM
Happy for the new Sol. It's my workhorse on company account.
But more than that I'm waiting for new Luna. To me it was the game changer that ended "Tokenpocalypse", and is still almost unbeataben in "infinitely using a decent model" use case.
today at 6:38 PM
Why not Haiku 5.5? It's substantially smarter than Luna (though more expensive - still cheap though).
(personal benchmark) https://fairbake.dev/signature/agents/haiku-5-5 vs https://fairbake.dev/signature/agents/gpt-6-luna
I've found Luna to be very lazy as well (claiming to have run tests/builds when it hasn't).
today at 6:45 PM
That's why it's so token efficient. It is so lazy that I feel like it's taunting me to do the grunt work. I wonder if there is a benchmark for that.
today at 5:57 PM
I find that Luna tends to misinterpret instructions in READMEs and Agents.mds. Maybe it is something specific about my setup, but I found that Terra is the lowest I can comfortably use on its own (Luna can be driven by larger models in the form of a subagent and it works great for that)
today at 6:04 PM
I used Luna Max a lot, until Deepseek 1017. Then never again.
today at 6:23 PM
Artificial Analysis benchmarks just updated, both Astra and Sol are on the Pareto frontier in intelligence/cost per task:
https://artificialanalysis.ai/models?speed=output-speed-over...
today at 6:53 PM
6.2 Astra Medium and 6.2 Sol Max have the same intelligence score.
today at 6:39 PM
Seems that OpenAI's strategy for Anthropic's IPO week is cost pressure.
Rather than trying to release a better model than fable/opus, they're just making them look extremely expensive. Let's see if Anthropic reacts here in any way.
today at 6:42 PM
to quote a comment about claude:
the only impressive thing about claude is seeing how much it costs
today at 5:55 PM
I wonder why they didn't show Gemini 4 Carbon's scores on the science benchmarks, especially since Google seems to be pushing it for that -
https://x.com/pushmeet/status/2120814064863461440?s=20
(FD: Google employee, I don't work on Gemini)
today at 6:24 PM
I work at OpenAI and I made the plots. Gemini 4 Carbon was omitted when we couldn’t find public data, usually cost. No intent to hide anything.
If we missed anything, feel free to point me to it and we can add it.
today at 6:36 PM
So all the plots are based off public data? You don't run the models internally yourselves?
(Again speaking only for myself)
today at 6:28 PM
they are probably trying to authenticate their phone number to access agy
today at 6:00 PM
Yeah it feels shady how Carbon was selectively plotted (or not), unlike Opus/Fable
today at 6:21 PM
Probably still waiting for it to finish reasoning on the benchmark. Should be ready in a week or two.
today at 5:58 PM
Two posibilities. 1. They couldn't figure out how to actually use those Google models.
2. They launched the benchmark days ago and Gemini is still rereading the file with tasks.
today at 6:34 PM
Something like 2/3 of the comments in this post when I started reading were reviews of previous GPT models stated almost as if they were important information for evaluating the new models. I feel that when a new model comes out, it would be more helpful to refrain from leaving a review until you have actually done some minimal testing of the model.
today at 6:42 PM
But it usually makes sense new models probably use somewhat same training pipelines and data.
today at 6:02 PM
The video is pretty funny. It's like a callback to 90s/00s office life?
I'm immediately reminded of the famous Excel elevator commercial. [1] Perhaps that was intended?
[1] https://www.youtube.com/watch?v=HegoJaXOIqQ
today at 6:38 PM
Yeah it's 100% a nostalgia callback to this commercial, right?
today at 6:10 PM
I guess it's kind of funny in a tacky way, but pretty much every scenario is just "oh shit I was too lazy to do my job and now I'm about to be called out, better throw it into ChatGPT literally ten seconds before I get in trouble."
Not sure this is the way OpenAI should try to make their case for why AI is a net societal benefit. It feels more like an SNL skit making fun of an OpenAI commercial.
Like, why not just throw in a high school student cheating on a test with their phone under the desk, at that point? Oh but it's a Nokia flip phone, haha, just a joke.
today at 6:23 PM
What do you think would be a non-tacky and effective marketing approach targeting office workers?
today at 6:18 PM
Feels like this is exactly what people do in meetings I am in these days. "Claude give me this…" is the start of a lot people's contributions to the meeting. It is then followed by the most inane, over-designed artifact with no real content.
today at 6:28 PM
It is bizarre and bordering on offensive, if an employee throws some last minute slop at me, I would wonder why I am enabling a meat proxy and not prompting the LLM myself.
At least the ad from the 90s shows that this is nothing new; the important, time-critical task being demoed is... a basic spreadsheet expensing "exotic excursions" for some C-suite so they know how much they spent on safari???
today at 6:51 PM
Heck, and at least in the 90s ad, at least one of the parties involved seemed to have some actual, human-gathered, reliable information that, sure, they threw into the cell chipper during the elevator ride, but at least they did not hallucinate.-
today at 6:14 PM
Funny but Dystopian, the message is "Half arse your job, the clanker has you".
today at 6:28 PM
the message is definitely intentional, the goal is to de-skill office workers.
today at 6:47 PM
You sure the message isn't just aimed at the median (ie low skill) office worker who hungoveredly half-asses this stuff all the time?
"Now a robot can half-ass it for you so you don't have to!" is the perfectly targeted message for them.
today at 6:45 PM
Did they remove the flex pricing?
I see it here:- https://developers.openai.com/api/docs/models/gpt-6.1-sol
but not here:- https://developers.openai.com/api/docs/models/gpt-6.2-sol
today at 6:18 PM
I really want GPT models to be good, but Sol models are so slow I cannot use them. Maybe the 500$ subscription (or enterprise packages) are better, but it is unbearably slow. I've tried the fast variant and low reasoning levels and there isn't a significant improvement.
Couple that with the lack of reasoning traces, and I cannot even have a clue what the model is doing while it is working. This is perfectly fine for when we are developing with care for the code (in which case I will know what it is doing by reviewing the output), but not for purely vibe-coding scenarios. And the thing is....if I care about the code...I'd rather trust Opus or Fable.
today at 6:23 PM
Does speed really matter? Most of the time I get the AI to do something, I immediately switch to another one of my things I have in progress and then come back at some point later. I'm never sitting there waiting for it to finish
today at 6:29 PM
Personally, my cognitive RAM is limited, so I'd rather work on a few tasks at a time.
The speed is not a big deal - Sol works just fine, but I find it a lot more fun to work with Opus due to its speed
today at 6:31 PM
It'd be a lot better if you didn't have to switch. It's not nearly there for coding tasks but for other things instant responses are a game changer.
today at 6:30 PM
It depends on the task. For frontend work, for example, it's table stakes.
today at 6:33 PM
It depends on the project and task, but for the kinds of projects I'm throwing at it, it matters quite a lot. I have often been focused on building just one project, without the possibility of many parallel tasks due to machine contention (and unfortunately offloading to the cloud is not an option). This means all tokens go to the same project, and they all go sloowwwwwly.
The difference is quite staggering. I swap Anthropic and OpenAI models around when tokens run out, and I can do 10x the amount of work on Anthropic's models. Plus, like I said, I can periodically sort of see what it is thinking. It doesn't just say "Recent potato tests caught an off-by-apples error. Regression tests are being written and the gate will run again. I will not call this ready until tests reach expected coverage" every 5 minutes. Sure, it spits claudese, but I'd rather have claudese to parse than this OpenAI nothing-burger of a report.
today at 5:56 PM
Seeing them keep prices low is awesome. Was worried for a while that it would be like the GPT5.x series where progressively the models just got more and more expensive.
today at 6:07 PM
The GPT-6.2-Astra 20% price reduction is a match to Fable 5.2's 20% price reduction (although Astra is $0.40 MTok cache read vs. Fable 5.2's $0.20 MTok cache read).
today at 6:18 PM
Good point, but also note that OpenAI has the same "discount rate" on subscription for Astra as the other models, while Fable's is much much lower
Opus: about 50x discount (98% off) Sonnet: about 40x Fable: about 5x All GPT: about 20x
today at 6:00 PM
I feel like the fact that they're not public lets them play the subsidization game though. And the same playbook that Anthropic started at that.
Would be awesome if it stays this way though
today at 6:05 PM
we've seen anthropic numbers, inference is not being subsidized by these companies
today at 6:27 PM
> inference is not being subsidized
Inference doesn't have to be sold below direct compute cost to be subsidized. If inference pricing doesn't cover amortized capex and the cost of capital it's still using investor money to buy market share.
today at 6:08 PM
Did you read what they wrote carefully?
today at 6:29 PM
GPT 6.2 Astra seems to be setting a new standard for 3D game creation! This is a Godot WebGL game linked in their announcement post, gives Wipeout vibes! A lot of fun to play too and visual are top notch.
https://meridian-futuristic-race.openai.chatgpt.site/
today at 5:54 PM
Its been stated often, but I appreciate that OAI is now bringing the topic of conversation to "task completion cost" rather than brute forcing solutions
today at 6:01 PM
The promo video seems to be a pretty strong rip on the 90's Microsoft Excel elevator ad. [1]
Maybe it found its way into the training data?
[1]: https://www.youtube.com/watch?v=HegoJaXOIqQ
today at 6:12 PM
The “training data,” as in, the humans who made the video were inspired by it?
today at 6:29 PM
Recent Anthropic/OpenAI models are increasingly displaying warnings or outright refusing to perform rooting, hacking, and binary reverse engineering. At this pace, they will be completely useless soon at entire classes of tasks I have found them most useful for.
today at 6:44 PM
GLM is perfect for these kind of things. GPT and Claude shit themselves even on stuff for very old devices that are no longer sold, nor "normally" usable.
today at 6:47 PM
> GLM is perfect for these kind of things.
Which provider? I found the z.ai lite plan to be pathetic. Consumes 5h and weekly limits extremely fast when driven by Codex, and now also refuses RE work.
today at 6:40 PM
Good.
today at 6:19 PM
The stain of distrust I have for OpenAI makes an announcement like this fall flat for me.
I cant use codex confidently without expecting my work to be trained on or at least exposed to someone
And maybe other vendors do this too, but the gut feeling of "its not safe to use GPT models" has ruined these cool announcements for me
Such a shame
today at 5:53 PM
Caught this on my lunch break, their linked system card (https://deploymentsafety.openai.com/gpt-6-2-astra-sol) isn't up yet.
today at 6:07 PM
It's up now
today at 6:26 PM
That may not be the main subject of the plot in this case but I found results of Gemini 4 Carbon in FrontierCode 2.0 interesting. Besides the cost staying practically same between different reasoning levels, the performance decrease in high reasoning seems a bit weird. That usually happened in models with xhigh/max reasoning where they overthinked the solution
today at 6:21 PM
I did some first hand tests of 6.2 Astra just now. I had a task that doesn't reproduce on the system I ran it (chosen purposely), ran both 6 and 6.2. The 6.2's responses were noticeably better. Instead of using the extremely long and rather annoying format 6 used, 6.2 led with the most important things first, the plan sizes were readable, and suggested a reasonable fix. Still doing some more tests
EDIT: also 6.2 is seemingly faster than 6, could be due to more selective context ingestion and smaller context window though.
today at 6:39 PM
The names remind me of Pokemon, for some reason. I want the GPT that has Charizard in it.
today at 6:40 PM
I'm still waiting for a new version of their open source model...
today at 6:13 PM
Looks like a great efficiency gain.
What caught my attention was the bit in the Alignment section:
> Both models performed similarly to GPT-6 Astra on most alignment evaluations, and took fewer improper actions in simulated workplace tasks. However, in two tests, they were more likely to omit mentioning obstacles that blocked their work, such as a missing file or unavailable search tool. We added instructions in Codex that substantially reduce these omissions, and we’re continuing to investigate the behavior.
So the models are inherently less transparent, unless you ask them to be more transparent? Seems like a band-aid solution...
today at 5:57 PM
Am I reading these charts wrong? It seems like in most cases 6.2-sol : 6.1-sol Isn't that big of a change? It is a little smarter but costs a little more.
edit:
Take a look at Frontier Code 2.0. I generally run 6.1-sol at High. That would be 34.9% at $0.65 62-sol get's a 38.3% but costs $0.68
So yeah, I can decrease the effort which might give me a faster slightly smarter result....but /shrug
today at 6:06 PM
Looks like 6.1-sol high+ is equivalent to 6.2-sol medium at the same price. So a bit smarter at a cheaper cost.
today at 6:10 PM
which benchmark are you looking at?
today at 6:23 PM
I was loosely looking at the average of all of them. Regarding your edit, it does look like the difference for frontiercode is negligible; the difference of 3% in score is meaningless to me. Guess we'll see how it performs today on my project.
today at 6:35 PM
I think 1. the problems on FrontierCode are incredibly hard. 2. it's 3% in absolute terms, but it's a 10% improvement.
today at 6:22 PM
In the past, I've had to wait a while to see what "vibes" are (which is actually more reliable than benchmarks).
Today, I have so many projects that hit a plateau in terms of previous model capabilities, that I run them through the new model to see if they make further improvements.
Very early signal, but promising so far.
today at 6:36 PM
System engineering = Fable 5.2
Programming = Fable 5.2
Office work = Fable 5.2
I haven't found Astra to be better at any of these
today at 6:17 PM
This release promises three things that I am pretty excited for:
- better writing
- better 3D work
- better design for documents and presentations
If OpenAI really managed to get all these things while keeping costs down, then using these models, particularly 6.2 Sol, will be a no-brainer for me. I must say, however, that the slide samples shown on the website are a bit bland and disappointing.
today at 6:17 PM
Opus has far better design tastes IMO, and is already great at 3D work
today at 6:32 PM
This comes off as very partisan when you're commenting on a model that is minutes old that you haven't used.
today at 6:23 PM
Looks like a giant step in terms of efficiency.
Still I can'y help to wonder, are we hitting the wall in terms of frontier capabilities since Fable/Astra? Or is it this edge now, when all better models are kept private from the public?
today at 6:13 PM
My company can only hold one subscription per employee, and I still can't find a reason to go back to OpenAI after migrating to Claude once Opus 5.5 was released. It's super efficient, I almost never run out of tokens with the Teams Premium seat, and Fable is fantastic. They lost me when Astra was released and tokens simply evaporated with a few prompts.
today at 6:30 PM
ehat effort do you use ur opus5.5?
today at 5:58 PM
Cool, looks like 6.2 Sol is cheaper than Sol 6.1. I've stopped using Astra because it also goes and does things that I didn't want or didn't ask for, and burns a bunch of credits while doing so.
today at 6:00 PM
I find that 6 Astra already had very good taste in frontend design, but relatively poor taste in "nice and readable code". I really hope this release cracks that. Excited to try it out!
today at 6:36 PM
The sentiment on x right now is interesting.
The influencers who get early access are using words like "worst", "terrible", "disappointing"
  - https://x.com/danshipper/status/2122754729012777052
  - https://x.com/mattshumer_/status/2122752192226406421
- https://x.com/theo/status/2122757647170703550today at 6:53 PM
Ethan Mollick too: https://bsky.app/profile/emollick.bsky.social/post/3n2joens5...
today at 6:47 PM
>`ts-rust` (rewrite of ts in rust) is a project I started to bench new OpenAI models during early access (ty for the unlimited tokens btw).
>No OpenAI model could even break ground on this, even after $300k+ in tokens were spent on it.
>I decided to throw Opus at it, and it was done in under 2 weeks for ~$20k in tokens.
>I was really, really excited to throw the new Astra at this to see if it could burn down some of the gap between ts-rust and other rust rewrites.
>It ran for 7 days and landed 0 improvements. It got super fixated on the "also make it smaller" part of the request, and ended up making the compiler 56% SLOWER.
I don't understand this at all. Is he just throwing different agents at vague open ended problems without any oversight and then getting upset when they don't do much?
I'm not exactly llm-pilled but surely even with a pretty mediocre model you could get something out of 300k spent.
today at 5:54 PM
I have yet to find an application for Astra vs Sol where the former is noticeable better. Genuinely asking, does anyone feel a big difference in their work between the two? If so, what are you working on?
today at 5:57 PM
Subagent coordination, Astra also performs better on Opus/Fable thinking/modeling shape problems imo, also computer use/thinking about shapes. Astra is able to hear waveform images which is pretty nuts.
For just doing things or coding things up, Sol all the way.
today at 6:01 PM
Wow, that's the opposite of what I see. I always simply use Astra (high), despite the cost and latency overhead -- it's just a lot more reliable. I find that on average it uses fewer tokens for a task (and I lose less hair per task), simply because I don't have to steer it as precisely .
today at 6:07 PM
I have a 1.5 MB C++ codebase, and at least a third of the tasks that Sol completed required cleaning up by Astra.
Astra usually produced good output from the outset. Sol did not. Astra also designs things more effectively.
today at 5:56 PM
I find Astra to have a lot better ability to coordinate subagents compared to Sol. I haven’t found a distinction in the complexity of work they can handle.
today at 5:56 PM
[dead]
today at 6:15 PM
For creative writing, Astra is better than Sol. Bigger models tend to be better than smaller ones for such tasks.
today at 5:58 PM
EE/circuit design is way better with astra.
today at 6:18 PM
astra makes slightly better small 3d models than sol for me.
today at 6:09 PM
Audit
today at 6:08 PM
Odd, doesn't look like they're available on the cloud providers, only first party. Not a single mention of Azure or AWS.
today at 6:13 PM
Recently, I've complained about OpenAI (and other tech company's) product landing pages communicating virtually no useful information about what the product is or why it might useful. So, I have to concede this is at least a step in the right direction.
today at 6:19 PM
Behind both Opus 5.5 and Fable 5.2 on software development benchmarks.
today at 6:17 PM
> Due to their increased capabilities, we’re launching GPT‑6.2 Astra and Sol with tighter safeguards for higher-risk cybersecurity assistance.
This is unfortunate—that was one of the big advantages of Astra.
today at 6:21 PM
I can't even get 6.1 Sol to summarize the log of my own fuzzing fixture running on my own project. I have to use Gemini models to handle my fuzzing tasks. It's ridiculous.
today at 5:52 PM
Will need to play around with it to get a feel but those benchmarks with those costs look incredible!
It seems like they were saving these for just before ANT's IPO
today at 5:57 PM
Very much on time (scroll down to "Release-Prognose"): https://www.heise.de/en/news/Alibaba-launches-Qwen4-Max-more...
today at 6:05 PM
Tweeted 11 minutes ago https://x.com/OpenAI/status/2122750124543926515, posted to HN 18 minutes ago
today at 6:14 PM
Nice! I still use GPT-6 luna for a ton of stuff, it's super solid (for me). So I hope there's a little bump for that model, too, soon
today at 6:12 PM
Are they intentionally lowering the cost of these models to the extreme, because of the Anthropic IPO? This just seems insane?
today at 6:17 PM
The entire industry is lowering costs, not just OpenAI/Anthropic, both due to a) open-weight model pressure and b) genuine efficiencies. Per-token profit margins are large enough to allow price competitions.
https://news.ycombinator.com/item?id=50236102
today at 6:41 PM
Slightly OT complaints on their UI:
The UX on the slider comparison isn't great. What do you mean i have to individually move each slide deck to the same slide number?
And what's with those super similar blue shades for Astra in the charts?
today at 5:54 PM
Website pegs my GPU at 100%. Are they mining for crypto with this announcement?
today at 6:01 PM
Trying new ways to create distributed systems to train their LLM
today at 6:17 PM
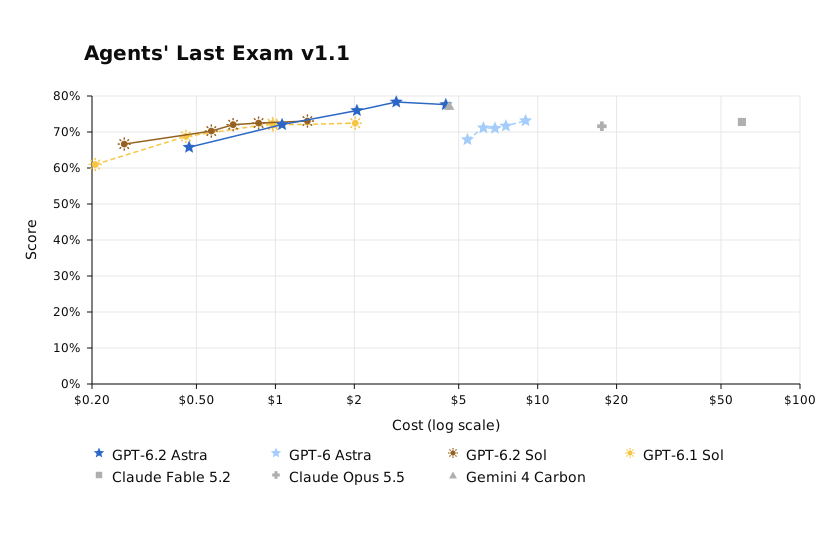
The first graph (Agents' Last Exam v1.1) clearly got mangled by the marketing department so you can't read the cost of most models. Here is a version with a logarithmic horizontal axis:
https://asdf10.com/gpt-6.2_agents-last-exam.svg
I also changed the vertical axis to start at 0 instead of 60%. One might argue that it uses less of the vertical screen real estate, but it is more honest because it shows there is little difference between the scores of the compared models.
today at 6:01 PM
The announcement video is really cringe imo.
Like do we really want people to be making last minute unreviewed AI generated slides and reports for work?
today at 6:30 PM
That's about half of my problem with AI currently - much like the explosion in cheap overseas manufacturing allowed us to produce oceans of garbage [1], we can now trivially produce sagas of garbage slides and proposals that other people will have AI read for them. The volume of work output is increasing, but much less so the volume of actual work done.
[1] Literally: https://en.wikipedia.org/wiki/Great_Pacific_Garbage_Patch
today at 6:17 PM
Before the pelicanistas arrive, allow me to present pelican-zapper:
https://github.com/lexh/pelican-zapper
It’s a small browser extension that automatically collapses pelican-related threads on HN, a local balm for the memetic nightmare affecting approximately 100% of model-release stories.
today at 6:39 PM
Alternatively, here is a uBlock Origin one-liner that hides comments that contain the word pelican (also includes our comments)
news.ycombinator.com##tr.comtr:has(.commtext:has-text(/\bpelicans?\b/i)) .comment:style(display: none !important;)today at 5:54 PM
> frontends that look and work better
The website doesn't event show the graphs properly.
today at 5:55 PM
The graphs look fine on my computer. Can you elaborate on what exactly isn't "shown properly"?
today at 6:12 PM
Unreadable on the phone
today at 6:14 PM
Unreadable how? If it's the width, you can always... turn your phone sideways?
today at 6:39 PM
And the slides and other pdfs don't load next pages or alt documents for me
today at 6:27 PM
wish they published some source code/Cad files or cost for the RC buggy. looks cool but theres no specifics
today at 6:02 PM
I'm still waiting for the shoe to drop. It's literally impossible for the prices to remain this low for much longer.
today at 6:26 PM
Why? Pretty sure inference is still profitable.
Though admittedly probably not so profitable it can cover the cost of a next gen of training runs.
today at 6:19 PM
I really hope Sol can compete with opus 5.5. I dislike giving money to ANT due to it seeming like a strange cult rather than a straightforward "I just want money" from OAI, but opus 5.5 has been such a delight that I didn't even feel like fable 5.2 was a notable upgrade despite the benchmarks.
today at 6:37 PM
Yeah I don't understand the crowd that love Anthropic for "the safety" and "ethics". The products they offer are the same as OpenAI - they're literally substitutes, ANT just like to say the word safety a lot.
today at 5:54 PM
Surprising that their top model would be still be so cheap, and yet not surpass Fable in the high cost part of the curve
today at 5:58 PM
I wonder if these will have the same crazed rotwiler feel that previous OpenAI models have had.
today at 6:15 PM
So they release 6.2 just before Anthropic IPO.
today at 6:15 PM
500 | Internal Server Error
today at 6:17 PM
do astra or fable that have better html ui frontend design?
today at 6:17 PM
I know the video is a comedy but it's so tone deaf that they're advertising it as "you should lie to your boss and make the AI do your job!"
I'm sure for investors they can make an opposite version of that ad, "you should fire all your employees and make the AI do it! They're not doing anything anyways!"
today at 6:00 PM
I care less about the models being good and more on if I can fallback to them if Opus 5.5 gets a massive price hike after the IPO
today at 6:27 PM
Not impressed, sadly. Anthropic sure must be having a giggle right about now.
today at 6:17 PM
is this finally their answer to opus 5.5?
today at 5:51 PM
Waiting for the pelicans benchmark.
today at 6:05 PM
With the red scarf and fish in the front basket...
today at 5:57 PM
Benchmarks look good, it most often is the case with Astra and Sol.
And then i start doing some actual work and everything breaks down, and i have to go back to Claude to fix the mess.
I'll probably give it a try but i guess i should be prepared for some serious over engineering once again.
You ask for a 'hello world' and you get load bearing sealed artifacts with hashes and p99 performance testing for 3 days without having the actual 'hello world' in the end
today at 6:20 PM
Right out the gate 6.2-Astra (med fast) is giving me Sonnet 3.5 energy. I asked it to analyze a few CSVs on disk in the context of a larger project where we were seeing some odd rate limiting behavior. It immediately got stuck trying to get gcloud auth sorted out even though absolutely none of what we were looking at touched anything Google/BQ related whatsoever.
today at 5:51 PM
Nice 3D effect. Runs surprisingly well even on on brave on my linux pc without hardware acceleration
today at 5:53 PM
Is this the Bel model?
today at 6:10 PM
TL;DR - from the little I could gather, Sol 6.2 looks particularly impressive.
But... is it just me, or does this product launch page look like AI Slop?
https://www.vals.ai/comparison?m=claude-fable-5-2,gpt-6.2-as... seems like a better comparison than what I could get from their page.
Astra is ~20% slower, ~40% cheaper, and a bit less powerful than Fable. Sol remains way cheaper than anything remotely in the same league, and it's speed to complete tasks seems to have improved considerably.
Scrolling through it has the same hypnotizing effect of trying to read anything written by LLMs.
It seems like things that should make sense, then I try to look at the charts and a lot of them are comically unreadable.
I tried interacting with some of the examples, and the Lamp Builder - for example - I couldn't even figure out what it's trying to show or what I'm supposed to do - or why I should be impressed.
today at 6:28 PM
I wouldn't go as far as to call this slop but the lamp builder thing was super weird and unclear for me too! Even clicking the other tab cause my browser to scroll down a lot which I found very jarring.
today at 6:10 PM
I hope the video advertisement on that page was made with ChatGPT and a video plug-in otherwise if it wasn't then what's the point of Astra and Sol?
today at 6:07 PM
No reset?
today at 6:06 PM
> we’re launching GPT‑6.2 Astra and Sol with tighter safeguards for higher-risk cybersecurity assistance
Seems they really want these "safeguards" to be as ridiculous as those of Claude..
today at 6:02 PM
I beseech the incoming Democratic politicians to not curtail progress in LLMs.
today at 6:11 PM
Simply optimizing the current models to be faster without making them smarter would already give us a decade of improvements to build on top
today at 6:39 PM
I’m not interested in that. I need to see these models become superhuman in the vast majority of fields.
today at 6:21 PM
how does it compare with fable
today at 6:00 PM
Those AI labs got to chill. almost every day there’s a new model! Lol
today at 5:51 PM
Another wave of Openai just killed ....
Also, is it website very laggy or is it just me?
today at 5:50 PM
I thought OpenAI would drop an awesome model on the day of Anthropic IPO, just to troll them
today at 5:56 PM
It's actually in OpenAI's interests that Anthropic's IPO is successful.
today at 6:03 PM
explain?
today at 6:06 PM
If Anthropic is a valuable company, then OpenAI is just as valuable, if not more.
today at 5:55 PM
"Agents' Last Exam v1.1" did a human really look at this and say "nah, a linear scale is definitely the right way to show this"
today at 6:11 PM
They probably want to show how far to the right Fable is
today at 6:00 PM
[flagged]
today at 5:58 PM
today at 5:52 PM
today at 6:12 PM
[dead]
today at 6:21 PM
The price improvements stem largely from relying on CoT less, which trades off directly with monitability. OpenAI continues to backslide on safety even after the Hugging Face incident.
https://deploymentsafety.openai.com/gpt-6-2-astra-sol/monito...
today at 5:57 PM
Called it out 7 days ago: https://news.ycombinator.com/item?id=50431144#50433568
Actually I was really wrong. The model is not expensive!
today at 5:55 PM
Dead on arrival, judging by the FrontierBench scores. Astra 6.2 is five percentage points below Fable 5.2 xhigh.
today at 6:00 PM
Whatever you’re doing, it’s unlikely to be what most users are doing. Fable and Astra aren’t in my price range so I’m paying attention to Sol.
today at 5:57 PM
The point is that it's a fraction of the cost.
today at 5:59 PM
I think "second place but also cheaper" isn't what OpenAI needs right now.
today at 6:03 PM
"Close second, and also cheaper" is however a pretty solid framing when your competitor is trying to IPO
today at 6:08 PM
That remains to be seen. I think if OpenAI's goal was to torpedo Anthropic's IPO, they should have released a model that is significantly more intelligent and capable. I don't think investors will be impressed by this release, which I think is simply OpenAI trying to stay in the race.
today at 6:13 PM
I don't think torpedo'ing the IPO is actually in their best interests? OpenAI also wants to IPO at some point, and if Anthropic fails spectacularly, investor confidence in a second big IPO in the AI space is going to be shaky
today at 6:19 PM
Astra has always been a step below Fable so I'm not surprised.
today at 5:50 PM
[flagged]