today at 7:41 PM
At this point if a Google PM handed me $100 and said "go figure out how to issue a prompt to Gemini 4 Argon" I'm only ~30% sure I could figure out how. The Gemini app in my phone only has 3.8 Pro as the latest model; it does say "Ultra" in the bottom left, but I really don't think I'm on the Ultra plan. How I would sign up for that, on a Workspace account, is beyond our brightest minds.
Its sad watching them try to keep up when they want nothing more than to crumble under the weight of their own bureaucracy, and at this point I'm not sure there's any hope for them.
today at 10:00 PM
This model is not for you or me. This model is for Google AI engineers to put on their perf review at the end of the year. How you find or not find it, it doesn't matter. It goes into the "designed and developed Gemini 4 Carbon Ultra Pro" paragraph and people get a promotion, get to keep their jobs and hope to not get replaced by Gemini 4 Carbon next year.
today at 8:17 PM
Model selector at the top drops down and shows
* 3.5 Flash-Lite
* 3.8 Flash
* 3.1 Pro
* 4 Argon - New
And honestly, the versions are hurting their case. I ask myself “how is the oldest model, the Pro model?”
This kind of bungled naming and versioning is the kind of thing I expect from Microsoft.
today at 10:31 PM
It's supposed to be from 'smallest' to 'biggest' not release date.
today at 9:10 PM
today at 9:51 PM
Also limits are horrendous on all plans I might as well instead use Fable that would cost me less
today at 10:01 PM
i hear this but i can't believe it. I'm writing multiple moderate apps. rebuilding entire distributions. not coming anywhere near hitting the limit. Pro plan (on a discount too). What am I doing wrong (right?)?
today at 10:46 PM
Im using pro on a discount. I got argon a few days after the release but the usage limits are worthless. Asking it for a simple review of a blog post blows through 50% of the usage limit. And in the limited experimenting I have been able to do because of that it also isn’t smarter than 3.8 flash.
today at 10:26 PM
How are you coding on the Pro plan without antigravity? Copy/paste?
today at 10:37 PM
I'm on a Pro plan and Argon is in Antigravity for me now for some reason. It wasn't available at launch so I'm not sure when they backtracked.
today at 10:42 PM
I'm on the Pro as well, haven't checked if argon became available, will tomorrow, thanks!
I noticed the usage on chat is absymal, but it could very well be that their own harness does a good job in caching and you can squeeze good usage out of it due to this.
today at 10:35 PM
I remember a year ago and a bit ago trying to get an api key for some Gemini ~3 model. I probably spent an hour trying to find how to get a key in AI Studio. Finally figure it out and got a key.
I needed batch mode. Oh but the key from service X doesn't support batch mode, you need to go service Y and btw there is no UI for that so you need to use an SDK or API (cant even remember anymore). Spend an hour figuring that out, then it turns out I can't use batch mode because I don't have permissions. Have boss spend an hour granting me permissions. Then service is unavailable every n requests for 5 minutes, so I have fuck with exponential back offs.
Glad to see they moved that experience to their consumer offerings lol.
today at 8:28 PM
It's at least not worse than Microsoft. Go and start a chat with Copilot. Which one? I don't know, they are all the same. Or maybe they are all different? All I know that if you start a chat in one interface, there is close to a 0% chance (but not quite) that you will find the same chat in another interface.
today at 8:30 PM
I had Claude write me a script to probe all the GCP Vertex models. I can say with confidence that I know how to call Argon, because Claude told me how, I did it, saw it was modestly better than Flash for my use case and I decided it wasn't worth the money right now, for this use case.
I'm fairly confident I can't call Carbon, and I am okay with that.
today at 8:30 PM
I just spent 10m trying to use this.
It is the most awful product experience I’ve had this year. How could they fuck it up this badly?
today at 8:43 PM
> I just spent 10m trying to use this
wow pricing has gone way up
today at 10:22 PM
today at 10:25 PM
Maybe ChatGPT could figure it out?
today at 8:14 PM
There's no 3.8 Pro. However, there's a 3.8 Flash that's only available with Pro or Ultra subscription.
today at 9:34 PM
Brilliant!!
today at 7:56 PM
Unironically it's easier through third parties. Cursor has had Argon available, but in our enterprise we cannot get argon from the gemini subscription because they have some weird license split going on.
today at 10:55 PM
Yeah I was using Argon in Cursor on launch day and it's become my daily driver for anything requiring moderate smarts or lots of prose.
Not surprising that Cursor is better at charging money for something that isn't an ad.
today at 7:59 PM
All I see is 3.1 pro and 3.6 flash, I just canceled the sub lol - those seem like half a year old and I'm too lazy to check - my workplace gives me access to all models in a harness anyways
today at 9:03 PM
today at 8:12 PM
I tend to wait until it shows up in Google AI Studio. That is there web interface at least, no idea for mobile.
today at 9:50 PM
I don't even read Google's release notes anymore. What's the point? The models are never available.
Now, I just go straight to the Hacker News comments. I've given up on trying to figure out how to navigate Google's labyrinth.
Their release notes have become like breakthroughs in graphene. I'll believe it when I see it.
Their go-to-market execution is just so broken.
At the beginning of this whole AI shift, when Google would announce a new model, I would try to get access, even paying for a subscription.
Then I realized it's just not possible.
Google onboarding is the new Gordian knot.
For Google, I think the announcement is the success criteria. And onboarding is somebody else's problem. And the problem is... that somebody doesn't work at Google, or are entirely disempowered.
If, someday, Hacker News comments indicate that a majority of individuals have figured out how to access these newly announced models consistently, I might take my precious personal time to navigate the labyrinth once more.
today at 7:28 PM
It is pretty clear at this point that the frontier models need only handful of tiered models.
1. Ultra - The best and the most expensive for showing off and government. 2. Pro - Almost best but substantially cheaper for most productive people. 3. Flash - Workhorse for everyone. 4. Lite - For the unwashed masses and peasants.
There is no need to attach anything to these labels. In fact industry could simply standardize these namings like SEMVER.
There could be an internal representation which could give specific number of the model but these companies should move on to be more like Chrome. No one knows or cares which version of chrome they are on.
For a lot of systems the real underlying version would matter because of reliability. That can be provided to those power users.
today at 10:07 PM
You could say the same about many products, but marketing is often about not making the tiering obvious. Just try to make sense of the naming strategy of Samsung TVs, and you'll either eventually give up or go insane.
today at 10:44 PM
Very complex naming is a feature in the entire monitor industry.
today at 8:13 PM
There's a tier which is just, "summarize things and do grammar checks, style tweaks, and boilerplate generation". Maybe this is Lite. It's like how computing requirements for most people nowadays is "run a browser".
today at 9:02 PM
>There's a tier which is just, "summarize things and do grammar checks, style tweaks, and boilerplate generation"
honestly, this tier is the 4GB model that ships in chrome and runs locally
today at 8:39 PM
It's a bit sad to think that 100 years from now the low tier models will still be better than us at grammar. They are getting better and we aren't
today at 9:16 PM
> It's a bit sad to think that 100 years from now the low tier models will still be better than us at grammar.
Not if you're a linguistic descriptivist.
today at 9:10 PM
depends on what being good at grammar entails. If it's just following rules, then you're not wrong. If it involves adapting concepts to novel circumstances, we're doing well.
today at 7:44 PM
Pro v Flash - I always thought of Flash as quick, Pro as slower, Chain of Thought enabled.
today at 10:18 PM
But Gemini (the app/website) lets you set the Thinking level for Flash or even Flash-Lite. And Flash with Low thinking is the default.
today at 7:49 PM
And that’s exactly where it starts to get murky, because this isn’t a clear gradient after all but a matrix of different qualities for different tasks. Reasoning effort levels are one factor here, but the whole speed vs. Quality topic is another.
today at 7:39 PM
Excuse me, I am a washed peasant thank you
today at 9:25 PM
You're in-between tiers, and thus don't exist. Please wait 4 days between washing and try again.
today at 7:57 PM
I do not agree.
As an example, Linux distros say, Ubuntu got its project "names" as well as SEMVERs. But people rarely use project names but uses versions.
You tell me, I use "Jammy Jellyfish". I will be like WTF dood. You tell me 22.04 LT (which is one I use), oh yeah, that's a good one.
Same thing here. companies can call whatever SOTA whatever they want. But in the end people will refer to them as just Gemini 4 or Ultr/Pro/Lite however people like to use.
Just leave it to company's discretion. Don't enforce anything. People will figure out how to call it.
---
And wtf, a peaseant?
I use your so-stupidly-called ultra/med/lite but in diff situations, and when I use lite that doesn't mean I am peasant, I am being sensible
today at 9:57 PM
Ubuntu's release numbers are not semver, they're year and month. 22.04 is the April release from 2022. Your LT is redundant, all 04 releases from even-numbered years are LTS. And people do frequently refer to Ubuntu releases by the code name, though usually just the adjective and not the animal - jammy, noble, etc.
today at 8:42 PM
For debian it's quite common to use the toy story name.
today at 8:13 PM
I think he was referring to us pheasants.
today at 8:09 PM
[dead]
today at 5:37 PM
Given how quickly the field is moving, showing benchmarks without releasing the model is quite meaningless. If they decide to release it in one month, there will probably be a stronger competition out there. And the benchmarks won't look as good.
today at 6:26 PM
100%. They don't even suggest a release timeline other than "we look forward to bringing Carbon to developers, businesses, and consumers soon". Claude and GPT-6.x will no doubt have improved versions by the time "soon" comes around.
Has there ever been a product category where a product release is valuable for a shorter time than with LLMs? Trying to build SOTA models seems like it'd be an exhausting hamster wheel to work on.
today at 7:01 PM
A lot of the work is carried over model to model, so I think the most comparable product is a live service game. Always have to be building on the last thing, and if you stop you'll essentially lose the entirety of the initial investment because you won't keep anyone's attention. Plus a healthy dose of "winner-takes-most".
Just. Yaknow. 100x the costs, at the least.
today at 6:44 PM
When every day matters to profitability, I'm really surprised providers do voluntary cyber security testing or government approval in the critical path.
To be honest, if I were an LLM provider I would be wiring up my release process to be fully automated so within 10 mins of the last bit of fine-tuning it got released and a blog post posted.
today at 7:02 PM
Google is in it for the long haul, not to IPO before they run out of money.
today at 5:46 PM
I can't tell if they're withholding access to manufacture some sense of scarcity but the delays are really prolonged. I'm nervous to use Gemini models anyway, as its attached to my Google account and I've seen too many people having their whole account banned for dubious reasons (with little recourse).
Also the whole "we're only releasing it to cyber defenders first" framing is weird, is any Gemini model an actual cyber risk?
today at 9:58 PM
Could it be TPU/GPU availability? ie, is it possible that it's more profitable for their compute to be serving Anthropic models, so Gemini customers are stuck with lower compute available.
today at 7:05 PM
They've always been realllly slow to roll out stuff outside the org when it comes to AI. Most googlers themselves likely won't have access to this model internally.
today at 5:49 PM
Isnt it about risk?
Just because you saw your friend move to a new country for a job doesnt mean you will make the same choices, even if you are similarly qualified.
today at 5:50 PM
today at 7:18 PM
It doesn't seem possible to actually release frontier models quickly any more. Given their cyber capabilities, playing nice with the powers that be is probably required these days.
today at 7:22 PM
Somehow OpenAI and Anthropic have been releasing new models on the day of announcement.
Seems like Google could do it too.
today at 10:19 PM
They have to announce it now because by the time they are ready to release it, it won't be the best at anything.
Anthropic and OpenAI are not releasing their best models for several months, because their second best models are still better than everything else available.
today at 5:53 PM
They released Argon shortly after announcing it, so I think some benefit of the doubt is reasonable here. They claim they're already evaluating it via the government.
I suspect they're announcing it for two reasons: to get ahead of all the leaks; and because it's earnings report day.
today at 5:57 PM
Doesn't Google have a particularly bad record recently at making their models publicly available?
Especially on their Plus tier for Gemini.
I think it's a fair concern that this might take weeks and trail Fable 5.5.
today at 5:59 PM
They released Argon shortly after announcing it, so I think some benefit of the doubt is reasonable here.
today at 7:48 PM
I've bought my girlfriend a Google ai plus sub because she's not a developer and just wants some search and image generation but the fact that she's still stuck on flash 3.6 is a joke, why would I keep paying for that at this point
today at 8:09 PM
If you have Pro or Ultra you could add her to "family", up to 5 people can share one subscription. Also up to 5 people can share the potential account ban. Otherwise cool feature, I recommend.
today at 6:36 PM
Not really[1]. I had access to Argon within an hour of the release announcement.
The Google AI Plus tier does not give better model access than free, it is strictly for usage limits. Same thing as ChatGPT Go (which currently only has access to GPT-5.6 Luna, same as the free tier too.)
[1] For consumers at least. IIRC google business/entreprise accounts have worse model access even in the business/entreprise version of Google AI Pro.
today at 6:06 PM
I think the majority of traffic is from Enterprise customerd that goes through their API. Their consumer facing products do lag, but I don't think they care.
today at 9:20 PM
As long as it's from US lab, it'll also have to go through US apparatus.
today at 10:49 PM
huh?
today at 6:49 PM
It makes the best case for why Anthropic isnt worth its potential valuation. Anthropics customers are almost only turbo nerds.
Google has the products, the brand recognition, the hardware, the data and most importantly a billion normies.
Google was always going to win this thing, although I wouldn't discount meta. The only thing that matters is mindshare and Anthropic and OpenAI have largely generated NEGATIVE sentiment, outside some fanboys.
Google and Meta can plop cute products into your daily driver apps and you wont know the difference.
today at 7:09 PM
If Google is going for the casual group of users, why do they make their AI offerings so hard to buy?
today at 7:26 PM
because selling inference is not their end-goal product, its just a milestone to continue to maintain positive public sentiment and attract talent
today at 7:51 PM
> its just a milestone to continue to maintain positive public sentiment and attract talent
Google’s talent is solid B tier in 2026. Better than IBM but worse than Microsoft and Amazon.
Even if Google had “talent” this talent wouldn’t be able to accomplish anything due to corporate politics.
today at 10:26 PM
I work at Google. My response to your comment would get me banned from HN.
today at 10:51 PM
I worked at Google up until 2 months ago. In my exit survey, the #1 reason I left: "Bureaucracy"
today at 7:28 PM
Thats kind of the brilliant thing, you dont need to seek it out. Their AI will just slowly get integrated into their products you already use. I'm more so saying that normies will use AI when it lands in the apps they already use. Google AI features have been popping up all over their ecosystem. Normies do not want claude code and they think Dario and Sam are both disgusting human beings, stictly off of vibes.
Anthropics only moat is vendor lock on Claude Code, especially if they cant maintain being the front runner of the frontier model space, this is a really brittle moat. Brittle moats wont attract strong investment at a 1-2T valuation (not to mention all the other fiscal unknowns).
I just want OpenAI and Anthropic to lose because they seem to be the ones going around saying they're going to replace peoples jobs, and usurp the value of human labor.
Id rather Meta and Gemini suceed who will genuinely just integrate it into normal products we already use. Their sales teams are not approaching my boss and telling them they can reduce their payroll burden by spending my paycheck on tokens and firing me.
Coding is going to be one of the smaller pieces of the AI revolution. People on this site are focused on it, but there are 10000x more opportunities outside of coding where Anthropic and OpenAI have zero presence. Anthropic might as well be an IDE company, Is jetbrains worth 2T? to signal that they can be useful in other fields because they know this is an issue.
today at 10:34 PM
> they seem to be the ones going around saying they're going to replace peoples jobs, and usurp the value of human labor.
I don't see why an alternative provider that is quiet but also scrambling to make AI smarter is any safer for jobs. Wouldn't we rather orgs speak honestly about the risks of the industry?
I find it odd that we talked for decades about companies being evil for covering up problems (chemical companies, etc), yet it turns out people hate the ones that talk about risks openly even more.
today at 7:22 PM
> Google has the products
Outside their most successful products (YouTube, Android, GMail, Chrome, Search), their products are usually worse than their competitors (e.g. GMeet vs Zoom)
> the brand recognition
Of not maintaining/outright abandoning their products, and making Search worse over the years?
> most importantly a billion normies
ChatGPT has 1.2B weekly active users, all the normies know what ChatGPT is but don't know about Gemini (outside the "AI Mode" stuff)
today at 9:19 PM
> (e.g. GMeet vs Zoom)
I dunno if that's a great example - I'm sure Zoom has more awareness in the zeitgeist, but from my standpoint it's an app most well-known for security problems and abusing OS conventions, while Google Meet just quietly and simply works whenever I want to call my mom.
today at 9:52 PM
Outside of their successful products their products are terrible isn't even an argument.
They have many successful products. Most have only 1-2.
Youtube, Android, Chrome, Search, Photos, Workspaces, Cloud, Fitbit, Pixel Phones, Waymo not to mention dozens of open source projects.
> Of not maintaining/outright abandoning their products, and making Search worse over the years?
You just said their products are terrible. They do shut the products that do not meet the bar. That is good thing.
> ChatGPT has 1.2B weekly active users, all the normies know what ChatGPT is but don't know about Gemini (outside the "AI Mod
No one needs to know what Gemini are. If they have used search they have used it.
today at 10:29 PM
The Gemini app has the same number of users almost as GPT app. Sundar said so today.
today at 7:08 PM
Sure, bug Google always seems to be unable to deliver good UX. UX matters if it's bad enough and there are competing options that are much friendlier and easy to engage.
today at 7:30 PM
Android is a UX, and so is gmail and calender. This is where 99% of people will use AI for the remainder of their lives. Very little of the forward looking value proposition of AI has to do with coding/harnesses. AI + coding is rapidly deflating as far as revenue potential, and TAM has been saturated and is possibly shrinking.
today at 5:19 PM
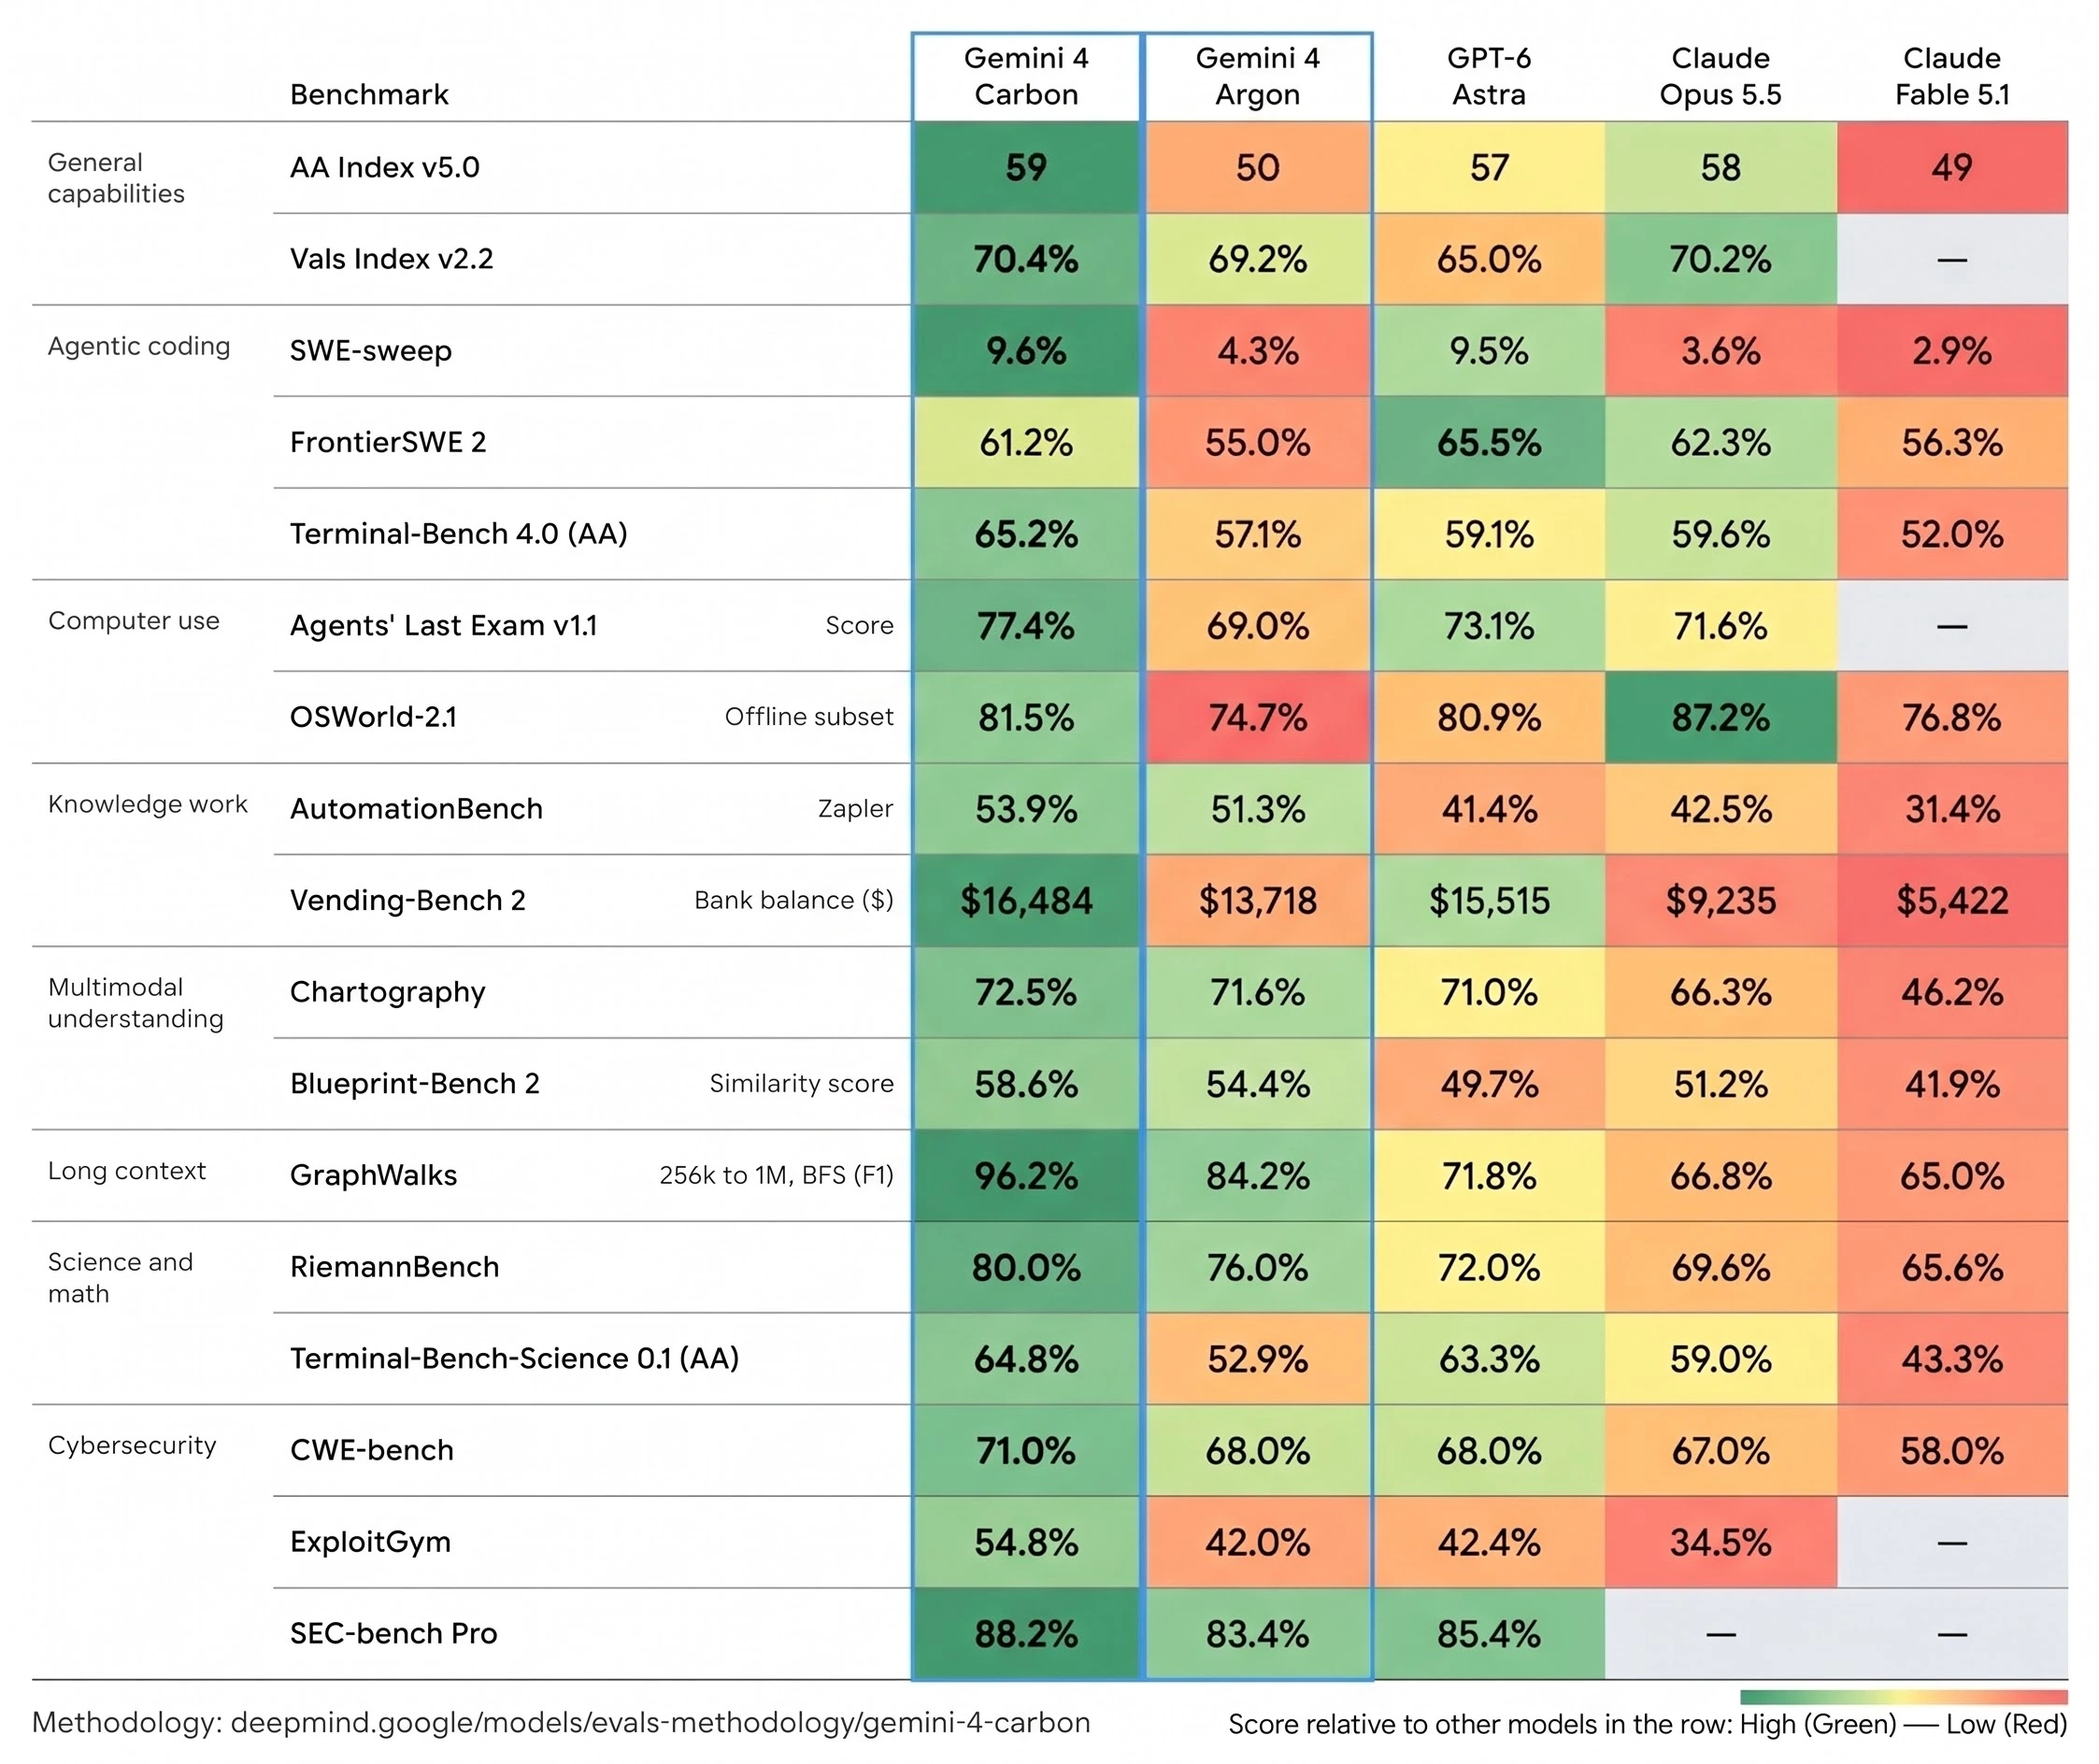
Benchmark scores recolored for readability:
https://i.imgur.com/IDFGuJU.jpeg
today at 5:54 PM
Serendipitous timing, but I've been building a little chrome extension [0] for doing exactly this sort of thing (highlighting tables automatically, especially when numbers don't necessarily correlate good=green, bad=red). Model pricing and comparisons are one of the main things I checked (low cost good, high benchmark score good).
[0] Practical Data (https://practicaldata.dev/ / https://chromewebstore.google.com/detail/practical-data/oeoo...)
today at 5:43 PM
Zoomed on the image and Imgur now also requires an app…
today at 5:45 PM
And is not viewable in the UK. Not hitting a lot of points in the shareability league
today at 5:46 PM
I am not @gavinray but I have downloaded the image from imgur and uploaded it to catbox.moe, hope this helps!
https://files.catbox.moe/2aqfk7.webp
(Edit: For some reason the previous jpeg link: https://files.catbox.moe/yjqa0a.jpeg wasn't working and catbox.moe was just downloading 4kb white screen so I converted the image to webp and reuploaded it on catbox)
today at 5:49 PM
today at 6:16 PM
Thanks. Nobody should be using Imgur anymore. I would recommend ImgBB as alternative, or your suggestion (Catbox):
Anyway, Imgur creates so many problems that it should be retired.
today at 5:58 PM
yeah, they've been quite logged-out hostile for a few years now. not quite as bad as instagram, but they seem to be holding that as their guiding-north-star...
today at 7:12 PM
Huh. Do people actually find that Fable-5.1 is worse than Opus-5.5 for any task?
today at 9:08 PM
Speaking for a user-facing use, not autonomous coding or agentic workflows: Fable 5.1 choice of words and general “words salad” expression are horrific. It starts not so good, then as the context grows (still way below any reasonable rotting threshold) it gets completely insane. It’s pointless for a model to be extremely capable if it gives you brain damage. I don’t know if it’s because of the watermark thingy, all I know is it gives me pure rage flares and every time I give it a shot I regret it. And there is no way to steer it away from this, anything I tried, both instructions and harness-wise, either failed or got forgotten/ignored after a while. I really hope the next Fable class moves completely away from whatever they did there to cause this.
Opus 5.5 in comparison is a bit more verbose and appears to settle on evaluations before the depth reached by Fable on very complex stuff, but is still vastly capable and I can read its output without wishing it had a physical form I could punch in the face.
today at 11:05 PM
I've started with Opus 5.5 last week. Roughly where do you start to see the context rot?
I've been experimenting with a project that is not growing real fast, but wondering about the risk as I try to make it do more.
today at 7:24 PM
I only use Fable when "knowing about more stuff" is important (like research, exploring ideas), but I find Opus 5.5 writes and expresses itself more clearly and is reliable for anything I throw at it, so I use it much more.
It's possible Fable is better, but since it word salads more quickly, it's hard to tell.
today at 7:28 PM
I find Fable 5.1 output to be borderline unreadable. Opus 5.5 on the other hand has been a pleasure to work with.
today at 7:22 PM
I've found its worse in most tasks, especially when ranked on a cost-per-task metric.
today at 7:55 PM
Fable 5.1 is good for better knowledge and tasks that require a more meticulous output, and it's objectively better at design and mockups IMO, but I rarely resort to it outside of that.
I generally use Fable for high-level blueprinting, architecture, and technical planning, and I tell it to write most of its documentation in a way Opus 5.5 will understand and maximally benefit from; with the added prompt for Opus to concede when a task would be better off to bring Fable back in. I've had ZERO problems.
today at 7:35 PM
[dead]
today at 5:46 PM
On one hand this looks like a joke?
On the other hand I'm a strong protan colorblind guy (red doesn't register to me very well at all).
today at 6:07 PM
Without color blindness it looks fine, green-yellow-orange-red. Having checked on a random website what a protan colorblind person might see, yeah, I get your confusion...
https://file.garden/auI5UdLIWwZSu5X8/pilestone.png - result of said simulation.
today at 6:39 PM
Thanks.
Also, I'm curious if you just asked an AI to _OCR the original image+update it_, or if you used a different process?
today at 9:10 PM
I used Gemini 4 Argon (High) from the Android app with the original image and following prompt:
> "Edit this image to color code the benchmarks scores using a gradient scheme that is immediately obvious"
https://share.gemini.google/g6LC7spTH0cO
today at 6:46 PM
What is SWE-Sweep?? Shocking to see such poor evals.
today at 9:26 PM
The only important benchmark is FrontierSWE and there it is of course 3rd. even after Opus 5.5 which is relatively old compared to their brand new model..
today at 6:12 PM
am i missing something or have they updated the page? the blue highlights and grey arent that bad to read?
today at 6:48 PM
Imgur is not available in the UK due to censorship.
today at 5:21 PM
Just remembered i haven't tried argon yet, they announced argon then and delayed releasing it, didn't even know they've made it publically available. I don't understand why google thinks this is an awesome strategy in a market where there are other really good models.
today at 5:46 PM
For what it's worth: Argon is a pretty good model, and this is coming from someone who just sticks with Opus 5.5 mostly across the board. For the current introductory price, it provides an exceptional value. Looks like they're trying to release Carbon (which is apparently a significant improvement) at the same price as Argon, which would be a crazy value.
It's worth trying if you have easy access to it (we use Cursor at work, so it was just a matter of picking a different model for me). Don't know if I'd go out of my way to get a Google AI subscription for it, but if Carbon ends up meeting these expectations, then it may be worth doing so.
today at 6:22 PM
It's important to note that Argon works best on Antigravity Harness: https://x.com/wenhaocha1/status/2114559544156205413
It's best to start with a relatively clean GEMINI.md too. Many configs optimized for Claude doesn't work well because Argon didn't have those same failure modes.
today at 8:02 PM
I've just renamed my files from CLAUDE.md to AGENTS.md I certainly won't do that again regressing back in the vendor specific direction lol
today at 6:24 PM
This would make sense. In our local coding agent battle system, Argon is tanking, and this is running on opencode, importing agents.md and claude.md.
today at 6:47 PM
claude.md is not needed anymore btw, claude now reads agents.md if it doesn't find the other.
today at 6:56 PM
Oh, sure, but isn't claude code still generating this by default? We're just inheriting opencode behavior.
today at 7:24 PM
?! When did that happen. Great!
today at 7:56 PM
I find their products confusing as usual. Does Antigravity sub work same as $20 Codex? Are the limits somewhat similar to ChatGPT and Claude?
today at 6:49 PM
Argon is the best writing model that's been released in a while
It's sad to see Carbon releasing at the same pricing because that implies Google is planning to do the thing everyone is doing: release promising model for subjective preference, RL-maxx a V2, replace promising V1 with V2 because it benchmarks better
Muse did it, Kimi did it, Deepseek did it, Tencent did it. No one seems to care abojt subjective preference anymore.
today at 5:51 PM
We're working on a battle system for local coding agents [1] and Argon is really bad. Literally the worst model in our initial ranking, and Deepseek Flash, Muse Wonder, Grok are all in there.
Top is Opus 5.5, followed by Fable.
[1] https://github.com/bottomless/agent-duel
today at 9:48 PM
I asked Gemini to review the repo. Apparent issues include:
  - Corrupted/dropped Gemini thought_signature (reasoning_details) in tool loops
  - Blinded model.api.id = "contestant" bypasses gemini.txt and serves Claude's prompt (default.txt)
  - Anthropic-only prompt caching
Prompt was:
> I read on hacker news the following, which does not match my expectations. Check if something in the harness or bench is hurting gemini perf.
followed by your post.
today at 10:01 PM
Wow, cool, thanks!
> anthropic only prompt caching
Anthropic has custom prompt cache requirements, but we've verified all providers are working well.
> Blinded model.api.id = "contestant" bypasses gemini.txt and serves Claude's prompt (default.txt)
This is wrong. We're serving default.txt which is opencode's default prompt. We are not serving a custom prompt for any model, including Gemini.
> Corrupted/dropped Gemini thought_signature (reasoning_details) in tool loops
We blind the reasoning details in the frontend because this would leak information. Some models summarize thinking while others provide raw thinking. I'll check if we're corrupting the thought signature that's actually sent to the backend.
So far this sort of looks like an example of Gemini being bad. Was this Argon?
today at 6:00 PM
That doesn't seem to match the arena.ai rankings, who I'm assuming has a far larger dataset of rankings than you currently hold.
today at 6:20 PM
You're right Arena.ai has far more data. Our data is actual local coding agent head-to-head battles, so I think our quality is far higher.
Their agents leaderboard is literally just randomizing the agent and looking at metadata like tool call errors. In my opinion, it's poor quality data in high volume.
Their web dev leaderboard is in cloud containers, most people don't run agents like that.
I ran a statistical test on our data. Deepseek vs. Argon. Posterior probability DeepSeek 4.1 Flash is stronger: 99.1%.
today at 7:04 PM
Have you tested older Gemini models? I wonder if their anti-distillation security measures are silently downgrading you to a less capable model.
today at 8:02 PM
Only 3.8 Flash which also didn't do particularly well.
It's possible, but we are getting real prompts from people on real projects, and the instructions about the battle are pretty minimal.
today at 6:51 PM
I've used argon via `agy` cli tool and was not impressed at all. However, I decided to burn up the remainder of my ultra credits on a visual reasoning pet project.
Argon in low and medium mode had higher quality results than it did when running in high mode, almost every time. My tasks involved the agent finding some details in a raster image and then mark it up with predictions about what it found.
Argon on high would do the work, and then a whole bunch of other stuff i did not ask for. All that extra broke everything else downstream from the analysis.
However, doing the same work with Argon in low effort was on par with results from Haiku 5.5 (xhigh) and GPT-6.1-Terra (medium). So, Argon low works better than Argon high, but for my tasks -- a very weak model relative to how google positions it.
I'm ready for Geimini Unobtanium!
today at 6:55 PM
Okay, this is interesting. We are hardcoding the effort (to improve data concentration), and Argon is hardcoded to "high".
today at 6:07 PM
Well, my perspective is somewhat narrow (I use it primarily for software engineering and pretty technical data engineering work), so it's possible that Argon is well-suited for the work I do but not for other tasks. I suppose it's just more data points to consider.
today at 6:20 PM
Our data is all software engineering run via local coding agents, but yeah your specific use case could be one where Argon is stronger. (Or your personal preference.)
today at 5:58 PM
This does not mesh with other battles like Arena where Argon is nearer to the top.
today at 6:21 PM
Yeah, we are doing something different and actually running parallel local coding agents head to head, something Arena doesn't do.
today at 9:42 PM
Have you considered that the harness might be the issue?
today at 10:47 PM
it's opencode
today at 6:51 PM
> local coding agents
what does "local" coding agents mean? Surely you're not hosting it..
today at 6:54 PM
Yeah, this is a new project so help me out here. I mean that the harness is running locally. I'm trying to distinguish this from arena.ai webdev arena, where they run the agent in a cloud container.
today at 6:26 PM
my anecdotal experience is that argon and muse wonder full are both a full tier below opus/sol.
today at 6:29 PM
So far in our data, there's no difference between Wonder and Sol 6.1. This is with wide error bars, as we're just getting started. Note this is Wonder, not Full as it's not on openrouter yet.
But yes, Opus is a tier above Wonder and Argon with very high confidence.
today at 6:58 PM
Argon is easily the worst model I've tried this year. From all the discourse I've seen, that seems to be the general consensus.
This might be the first comment I've ever seen saying something nice about the model.
today at 7:17 PM
Haven’t tried opus 5, sol 6 or haiku 4.5 I see
today at 5:44 PM
They’re not the only ones to do it, so I’m guessing their idea is to double-dip attention.
For me it also works the opposite way, when it actually comes out eventually it’ll already be old news.
today at 6:24 PM
I agree. Announcing a new model without immediate availability or a definite release date seems confusing than just doing it later. When Carbon is made GA, OpenAI or Anthropic might just release their new model, and we'd be like: Carbon what?
Having said that, I don't see people excited about using Argon so far, so that might be why Google is announcing this to hype Gemini up a bit.
today at 10:14 PM
Today was their earnings day. They could have been trying to justify their AI Capex. Their earnings were not good otherwise.
today at 7:25 PM
great writer, starts forgetting instructions around 80k context in my experience
today at 6:34 PM
Argon has been publicly available for weeks to Ultra users.
Anthropic has been doing this with Mythos for quite some time...
today at 7:17 PM
Argon has also been publicly available for the same amount of time for Pro users.
I don't understand why HN is so surprised to have an announcement for model existence and a follow-up announcement for model availability. It's really not that unusual, as you say Anthropic has done the same, probably others too (though I can't remember)
today at 10:27 PM
Because Google’s models have been a disappointment for so long (Argon tentatively excluded) that nobody is excited to read a press release from them stating a new one is coming out “soon.” There’s no hype when your product to date (tentatively pre Argon) has been inferior for a “long time.”
today at 8:16 PM
Mythos has never been publicly available.
today at 6:55 PM
They finally gave the $20/month pro tier access to argon in antigravity so I tried it a few days ago on one small thing and ...
it actually did really well.
But it still annoys me: I told it to _tell_ me something, and instead it _implemented_ the something. The previous models were way too eager to just jump in and do and this one seems no different. But the optimization it identified was both really solid and just a good engineering choice, and better than what Opus had been suggesting.
It also gave pretty good feedback on a bit of writing.
today at 5:36 PM
it’s pleasant
today at 5:42 PM
> it’s pleasant
for whom?
today at 6:07 PM
I paid for their lowest-cost subscription, thinking that it would give me a small quota of use of their most recent flash models. Instead, they give me an unnecessarily large quota of their old models, which I have precisely zero use for given that open-weight models are better and cost next to nothing.
Consequently, I have zero intention of renewing my Gemini subscription. What a dumb business choice they made.
today at 6:05 PM
It's Google. They can't help themselves. This is what they do.
today at 5:44 PM
In this age of constant change, I am grateful that at least I can still rely on Google for confusing, ever-changing product names.
today at 6:31 PM
They should at least tell us the atomic mass they're using.
If it's based on carbon-14 it will lose half its model weights in 5,730 years; if it's based on carbon-12, it's a stable release.
today at 6:39 PM
By the way things are going in the industry, I think Gemini 4 Carbon's lead will only persist for the half-life of Francium-223.
today at 10:20 PM
Depends. If it is uranium, the lead will only continue to increase.
today at 11:02 PM
holy shit lmao
today at 8:00 PM
Is Gmail still in beta?
today at 10:48 PM
RIP Google Inbox
today at 9:53 PM
I think it's called Google Wave nowadays. Wait ...
today at 10:13 PM
It was only in beta for 5 years. 17 years ago.
today at 6:04 PM
Next version: Gemini Tokyo Drift
today at 9:48 PM
Vin Diesel pulls up in an OpenAI NASCAR with Sam Altman in the passenger seat, tells us we're all family and transforms in to Optimus prime, a mobile data center
today at 9:54 PM
(Dario is later found in the trunk ...)
today at 8:49 PM
Gemini 4 Cabron
today at 6:31 PM
Gemini Fox on Socks on Knox on Box.
today at 10:52 PM
Gemini Super
today at 6:05 PM
Gemini: Capricorn
today at 6:10 PM
today at 9:32 PM
Gemini: It's Morbin' Time
today at 7:07 PM
Gemini: doomsday
today at 7:03 PM
"Introducing Gemini One, the sequel to Gemini 4."
today at 7:26 PM
Followed naturally by Gemini Series S and Gemini Series X.
In all seriousness, if Google must continue gambling on pre-train runs, at least have a useful naming scheme. Like the month it was post-trained and the parameter count. At least that’d provide some insight.
Gemini 2T 10/26, bit of a mouthful but is it truly that much worse?
today at 8:43 PM
Bold of you to assume it will still be called Gemini
today at 10:02 PM
Gemini XP
today at 9:15 PM
today at 6:11 PM
Gemini - Alignment Drift
today at 6:18 PM
Gemini Hit Pursuit 2
today at 5:52 PM
How is this any different than terra, sol etc or leopard, yosemite etc, or model x, y, 3, s ..
today at 5:58 PM
Don't know about the leopard and model x, but at least in the case of OpenAI luna > Terra > Sol > Astra is a pretty obvious size progression.
But I come from a latin language background, so maybe I'm a bit biased there.
today at 6:07 PM
At the risk of taking a geocentric position, my gut feel is Terra -> Luna -> Sol -> Astra. Sorting algorithm is distance from observer.
Size wise Astra is not categorically bigger than Sol, both in absolute terms and the observed size.
today at 6:52 PM
Astra is latin for "stars", so basically the Galaxy (or Universe as a whole) which is categorically bigger than Sol, the sun, a single star.
The naming makes perfect sense to me, the sorting algorithm is size, both for the names and for the models themselves. Smaller things represent smaller models, and vice versa.
today at 7:00 PM
> the Galaxy (or Universe as a whole) which is categorically bigger than Sol, the sun, a single star.
I would need to be a complete moron to argue with this. Humor me, however. My Latin skills end at remembering "Romani Ite Domum" and English is not my first language.
My layman reading of the names: there is one Terra, one Luna and one Sol => "Astra" is singular.
Now that I googled it, I understand that "Astra" literally means the "Stars" category. I would not have thought that they called a single star "Astrum". On the other hand, I am not sure if it means "Galaxy" in modern sense, but we're entering Roman Astronomy territory, where I am even less knowledgeable than in the language.
Sol is a star, so having a dedicated Stars category on the naming scale makes less sense. Treating Astra as Stars set without Sol, the "distance from observer" argument still kind of makes sense.
today at 7:31 PM
> My layman reading of the names: there is one Terra, one Luna and one Sol => "Astra" is singular.
That is incorrect. "Astra" is Latin for "stars" (plural). The singular would be "astrum".
today at 9:07 PM
Ad Astra. To the stars.
today at 10:31 PM
Size is by far the most obvious one, at least for me.
today at 6:27 PM
Yeah, this was my initial thought as well... I guess they didn't ask anyone before choosing the new naming scheme. But that isn't particularly surprising.
today at 6:41 PM
It doesn't help that the moon and sun have roughly the same apparent size in the sky
today at 6:59 PM
Why on earth (no pun intended) would anyone do this?
today at 8:27 PM
[dead]
today at 6:05 PM
    Luna  = Moon
    Terra = Earth
    Sol   = Sun
Astra = Galaxytoday at 6:11 PM
I didnt know this but apparently Astra is the plural of astrum (latin for star).
today at 6:32 PM
Cannot wait for Universe and Multiverse levels.
today at 8:03 PM
In the multiverse version, the model isn’t any smarter, but it’s evil.
today at 8:53 PM
Only if it has a goatee, which is how we know Robert Downey Jr's Iron Man and Benedict Cumberbatch's Doctor Strange were only the heroes of their own narratives, and nobody else's.
today at 9:08 PM
Or perhaps they'll release Supernova, then Singularity to market their ASI model.
today at 10:49 PM
“Let there be light.”
today at 6:08 PM
Astra means star, like the Sun
today at 11:09 PM
I went by their illustration of GPT 6 Astra that looks like a spiral galaxy[1].
[1]: https://openai.com/index/gpt-6-astra/
today at 6:17 PM
"Stars", if I'm being pedantic.
today at 8:50 PM
Not pedantic, the plural is the point. More than one star (Sol).
today at 6:41 PM
Good God, what has happened to people here? You literally wrote that Luna is greater than Terra, Terra is greater than Sol and so on.
today at 6:45 PM
Maybe just read this like an arrow?
today at 6:34 PM
today at 7:17 PM
Astra > Sol > Terra > Luna seems clear enough to me
Leopard (10.5) and Yosemite (10.10) both came with clear version numbers
Model X and Model Y are siblings which do not have a clear hierarchical relationship
Gemini 4 Carbon and Gemini 4 Argon are rather difficult for me to tell at a glance
today at 8:04 PM
Confusingly, Carbon is another model in the same size class as Argon. Every other lab would have just called it Gemini 4.1 Argon.
today at 8:40 PM
AFAIK they are all (Barium, Argon, Carbon) different checkpoints of the same (ongoing) training run
today at 6:41 PM
Luna/Terra/Sol/Astra make perfect sense, it indicates model tier/size with larger celestial body representing larger model.
Same for Anthropic, consistent model tier naming reused across model generations.
Those are just like i3/i5/i7 or M-series Pro/Max/Ultra.
But Carbon seems to be full replacement of Argon announced two weeks ago, they're same price. So Argon doesn't mean anything, they just picked random element.
today at 9:09 PM
Both openai and anthropic names feel much more confusing than cpu names to me.
They'd be fine except every named model has multiple numbered versions, with no consistent relatioship between cost or capability corresponding to the version numbers going up or down.
today at 8:33 PM
Could it be an alphabetic system like Ubuntu's?
today at 8:45 PM
I thought the obvious next one would have been Boron then
today at 6:35 PM
FYI, Model S, 3, X, Y is an acronym for S E X Y.
today at 6:41 PM
Lol feeling so dumb rn. How have I not noticed that before and how such an unserious guy is the richest man on earth?
today at 8:49 PM
The only hindrance for him was that Ford still held an automotive category trademark for Model E, hence Tesla had to go with Model 3.
today at 7:08 PM
He is extremely unserious. Did you miss the part where he cheated at Diablo to try to seem to be some kind of dedicated gamer? Or, y'know, the whole Cybertruck? Or the "pedo guy" comment after his harebrained submersible idea went nowhere and a regular diver saved a bunch of Thai kids?
He's always been deeply unserious.
today at 8:46 PM
And DOGE
The pedo-guy comment though I think was him being serious, unfortunately.
today at 8:56 PM
And all the 420/69 references. And doing "let that sink in" as a live-action bit.
today at 9:34 PM
Just that Z was on the market before 3 was, right?
today at 7:58 PM
Oh my god...I just realized SpaceX = Space Sex?
today at 8:42 PM
Nah, Elon is well reported to have been crazy about "X.com" since ~2000 and thus it makes sense it got incorporated into SpaceX name
today at 5:54 PM
Would it have been so hard to call it Gemini 4.1 or 4.5?
today at 5:57 PM
Then how would you compete with Anthropic and OAI with such boring names?
today at 7:19 PM
Is this was xai isn’t winning because they still use numbers for grok releases?
today at 7:16 PM
Do both like OAI and Anthropic do.
today at 6:29 PM
terra/sol or opus/haiku give an indication of size (the sun is bigger than the earth, opus is larger than a haiku). Carbon is smaller than argon (periodic table speaking), so that's no longer a helpful way of thinking about the model sizes...
today at 6:15 PM
today at 8:19 PM
It does more than merely being different, it also collides with the name of another Google project: the Carbon programming language.
today at 10:37 PM
I cannot figure out how to use anything better than 3.1 pro even on a paying account. There’s 3.8 flash and 3.5 flashlight. I can’t figure out which one is better so I’ve given up trying. It’s just too confusing. there’s too much competition for this type of confusion for the customer.
today at 10:41 PM
3.8 flash is probably the sweet spot for most of your use cases. I’ve tried argon once or twice, and haven’t noticed it being better than flash for my dev tasks. Likewise, DeepSeek 4.1 Flash still seems better than any Google model I have access to.
today at 7:58 PM
Don't worry, the name was chosen as a reminder to everyone of the environmental impact.
today at 10:01 PM
Yeah...some people complain about OpenAI and Anthropic's model naming schemes but at least it's fairly obvious from the names how they scale, how is ordering for Argon and Carbon supposed to be interpreted? And there's the 3.x and 2.x models which I don't think have elemental names (at least not public ones). The obvious atomic number or standard weight approach doesn't work.
today at 6:38 PM
True. And if Carbon (6) is better than Argon (18), wouldn't that make Hydrogen (1) the ultimate Gemini model, or will the next model jump to another random element?
  O, B, Sc, U, Re?
Ra, Nd?today at 7:52 PM
i'm also confused. my speculation is they trained a lot of different versions/revisions of models. maybe they're different base architectures, maybe they're different pretraining sets, or maybe they're different RL/post training regimes, and we're just seeing a few of them. still not sure what the names would mean internally though even in that case
or I'm dumb and its just elements with names starting with A, B, C
today at 7:32 PM
I am surprised there is no Gemini: will return in Avengers Doomsday.
today at 8:36 PM
This can't help but remind me of the USB organization's ridiculous naming.
today at 5:51 PM
Argon - first version, Bismuth - internal, Carbon - second version for the public if I had to make a wild guess.
today at 6:01 PM
Other sources say that what was publicly released as Argon was already the second version named Barium internally. So there was a separate internal Argon and public Argon was Barium. Not confusing at all for them! https://www.reddit.com/r/GeminiAI/comments/1x292ly/a_new_che...
today at 6:58 PM
The internal joke was that we're even scaling the off-by-one errors; Gemini 4 was not the fourth major model version.
today at 6:10 PM
Still better than Anthropic. If I create someday doomsday device, its turn off code will be to sort Anthropic models by strength given only their names, without access to the internet.
today at 6:42 PM
Before Mythos/Fable they were simply size-ordered. A Haiku is a small poem of 3 lines, a Sonnet has 14 lines and an Opus is a larger work.
I suppose a Fable is seen as larger. But some of them can be quite short, and not generally considered poetry.
today at 6:30 PM
I found Anthropic to be pretty intuitive.
today at 6:09 PM
Clearly, Google has already fired their marketing department and Gemini sucks at this job.
Maybe it thought the names are clear and intuitive (for an LLM perhaps).
today at 6:59 PM
Alphabetically sorting chemical elements sounds like something _only_ a marketing department could think of.
today at 10:48 PM
Hmm..they did come up with Bard.
today at 7:14 PM
Literally. If only elements came already presorted by some kind of a key already...
today at 6:52 PM
This naming strategy is bizarre.
There are no good elements for D; Dysprosium is the only one, and it's a mouthful. There are no good elements for E; Europium is the only one and would seem political. Is Fluorine their next release? (And then Gallium or Gadolinium?)
After Carbon, they should just update to Gemini 4.1 or 4.5 or whatever, and drop the random unrelated elements.
today at 8:47 PM
I don't think calling a model europium will be seen as political if it is a clear line of alphabetical animals, but who knows what the fine president can cook up
today at 7:23 PM
Deuterium?
today at 6:02 PM
today at 6:23 PM
Ah, so the next will be Dubnium
today at 7:07 PM
Dilithium
today at 5:56 PM
this captured the sentiment of my first reaction as well
today at 6:03 PM
Atleast we stopped hearing "copilot"
today at 8:05 PM
Amen
today at 9:12 PM
What's so confusing? Gemini is a constellation. Constellations are likely made of carbon and sometimes are made out of flash. And sometimes there's argon involved. Seems to make perfect sense to me. ¯\_(ツ)_/¯
today at 6:17 PM
I don't mind Carbon, Argon kind of throws me off because my brain autocompletes to Argonian... I still have no idea what the different ones from OpenAI mean. Can we just go back to "Silver, Gold, Platinum" for naming things? Something simple we've all understood, always.
today at 7:19 PM
Reading the Argonian reference made my brain immediately think “The Lusty Carbonian Maid”
today at 8:01 PM
Oh man, I just looked it up on my phone (still at work LOL) and I have go to go back to reading books when I play Elder Scrolls, I always seem to read only the ones without the funny stories in them for some reason...
today at 8:19 PM
Argonian* Maid
today at 6:24 PM
I'm kind of disappointed they haven't hit on releasing some models under the Alphabet name. That'd really stir things up. Then maybe Nest after that.
today at 5:54 PM
Ah yeah, Carbon it's so OBVIOUSLY a superior element to Argon!
today at 6:06 PM
You must have missed Mendeleev's less well-known Alphabetic Table of the Elements!
today at 6:11 PM
I think some sarcastic responses to Mendeleev at the time actually suggested this.
today at 6:05 PM
today at 6:06 PM
[dead]
today at 11:00 PM
today at 6:13 PM
Anyone still remember Bard? Google would probably desperately want us to forget lmao.
today at 6:59 PM
I really liked Bard as a name. IMO it’s much better than Gemini. Not sure why you think they desperately want us to forget it :)
today at 7:34 PM
Becase it bombed as a product in a comically bad way? They immediately rebranded.
today at 7:28 PM
So they can reuse the name for another product, duh
today at 5:28 PM
Perhaps someone should tell the Gemini team about these models. When I open gemini.google.com I see 3.6 Flash and 3.1 Pro.
today at 6:24 PM
It's all moot soon:
Updates to your Google AI Plus plan
We wanted to let you know about changes to the models that you can access with your Google AI Plus plan.
Starting on 1 3 N o v e m b e r 2 0 2 6 , the ability to select Pro models in both the Gemini app and AI Mode in Google Search will only be available to Google AI Pro subscribers and above. You'll still have access to our latest Flash-Lite model and Flash, built for speed and intelligence. Your previous chats using the Pro model can be continued with a different model.
To learn more about these changes, you can visit our Help Centre article for additional details. You can manage or cancel your subscription at any time.
Thank you for being a Google AI Plus subscriber.
today at 10:37 PM
For search I am perfectly happy with 3.6 Flash, its fast and servicable, and maybe being too smart is almost a problem for search and research. Mostly the edge google has here is that websites blocked for claude or chatGPT (if it respects the block) are unblocked for gemini.
today at 6:02 PM
I have a pro subscription and got Argon about two weeks after the announcement, I'm on the annual plan, got the 30% discount by switching it from monthly. Usage on antigravity is not included, usage via chat is absymally low. It's a good model though.
today at 6:21 PM
It should be available on Pro in Antigravity now.
It has a seperate weekly limit that is very low. Maybe it can be pulled off that usage tier and just regular usage since Carbon is being released?
today at 7:22 PM
I have a pro subscription and still don't have Argon. I can only access it via API.. I guess I can set antigravity up with that.
But it just all seems so tedious when codex and Claude are so painless.
today at 6:24 PM
Now if only I could sign up for a pro plan…
Unfortunately their plan structure is on par with their model naming.
The plans that allow for own domain and the plans that allow for sane AI use are mutually exclusive
today at 7:21 PM
My mother travels across two countries often. As a result she can not but Youtube Premium or any AI Pro plans because Google can't detect her country. The pricing in both countries is same. She wont even mind paying the highest plan.
today at 6:10 PM
I have a yearly plus subscription and I am still seeing 3.6. I am not renewing it once it expires. Why not give subscribers a small usage quota of their latest flash models?
today at 6:14 PM
The borg cube does not understand customer satisfaction.
today at 7:10 PM
Clearly! I was a happy customer, but that decision made me go through the effort of setting up a pay-as-you-go inference service with open-weight models, which I didn't want to bother learning how to do. But now I am perfectly happy with them and lost any interest in Gemini.
I bet I am not alone, either.
today at 5:48 PM
Only available to Google AI Pro subscribers. Google AI Plus hasn't got Gemini 3.8 Flash nor Gemini 4 Argon.
today at 6:26 PM
What's then the use of the Plus subscription?
today at 6:37 PM
Same as the ChatGPT Go: higher usage limits, more image and pdf uploads, more tools
today at 6:57 PM
ChatGPT Go gives you access to Sol which is much better than the ancient 3.1 Pro.
today at 9:39 PM
I agree, I don't think Plus is a good value proposition
today at 7:34 PM
But also no storage
today at 9:27 PM
Oh okay. Though OpenAI's model (GPT-6 Luna) seems a lot better than Google's (Gemini 3.5 Flash-Lite), so I don't see why anyone would pay for Gemini AI Plus.
today at 8:06 PM
Same. So after their now third announcement of a new model while locking their own customers out of it, I've just unsubscribed
today at 6:11 PM
They recently made it so you're stuck on 3.6 Flash if you don't pay them enough.
today at 6:48 PM
Note this is also true of OpenAI and Anthropic too (except Anthropic doesn't have a tier between free and all-models-available)
today at 6:52 PM
Disingenuous to not mention what plan you are on.
If you are talking about free versions, OpenAI and Anthropic also have a difference between free models and models available to 25$-tier plans.
today at 6:54 PM
No, not free. I'm on a paid plan.
today at 9:24 PM
Still not saying which paid plan. I don't really understand why you think that doesn't matter. Google is not the only company to have different model availability for different plan tiers.
today at 8:26 PM
My workspace account is "Expanded AI Access" and can't access any Gemini 4 models. Disingenuous to ignore the fact that you can't even sign up for Plus/Pro/Ultra on a non-personal account when talking about "what plan you are on".
today at 9:36 PM
I didn't ignore anything. I chastised for the missing information and gave a potential reason (which could totally be wrong for who I was replying to, which I acknowledge by saying if).
Thanks for sharing your experience though, it's a more substantive piece of information than who I was replying to.
today at 5:53 PM
I'm really starting to get annoyed by the fact that all companies are timing all their decisions according to the stock market.
Doing this two hours before today's earnings report.
It's probably going to be a terrible earnings call in terms of capital expenditure, cash flow and new borrowing.
today at 6:13 PM
> It's probably going to be a terrible earnings call in terms of capital expenditure, cash flow and new borrowing.
Now you know why they released it just before the earnings call.... :-D
today at 9:46 PM
good call .. turns out except on the "capex" maybe, which was actually lower than expected ( though this makes the neg. FCF of 9 Bio$ even look less good!)
today at 5:07 PM
> Reducing shortcuts and loophole exploitation: With Carbon, we further mitigated shortcut attempts in training while ensuring high-quality coding performance. Carbon reduced successful cheating on Terminal-Bench 4.0 to 0.0%, with attempts to cheat dropping to 0.4% — all while improving overall accuracy.
This is probably the single most important thing to make frontier models usable right now, so I'm happy there seems to be some progress. This was the previous Gemini's biggest problem IMO
today at 5:49 PM
[flagged]
today at 6:16 PM
>Resisting prompt injection: While Argon previously led the Gray Swan’s Indirect Prompt Injection (IPI) Benchmark in prompt injection resistance with a very low 0.7% attack success rate, Carbon achieves 0.0% — resisting every evaluated attack attempt.
"We patched every vulnerability we knew". Meanwhile, prompt-injecting Argon (or any other model) is still trivial, and Carbon won't be an exception. Because the attacker is not limited to things Google has evaluated.
AI shops are blind to anything that's not a metric.
today at 6:19 PM
Not just AI shops. All large organisations, software or otherwise...
today at 5:44 PM
Sooo... Is Carbon 4.1? Or is it different to Argon 4 somehow? Different model? Or point update?
Is Argon "pro" and Carbon "ultra"?
Is Argon obsolete now? Does Carbon replace it or live alongside of it?
Very confusing naming!
today at 7:22 PM
1. "Building on Gemini 4 Argon". 2. Same price. 3. Relatively short time between releases.
Makes me think it's further post-training of the same model.
today at 7:42 PM
IIUC, that was all the Flash releases from 3.5 to 3.8
today at 7:23 PM
For Gemini that is a foundation model version 3.1 3.5 4 etc. and there is checkpoint on evolution of those specific models. Gemini 4 had Argon - B<> - Carbon and who knows they might have Dysporsium or Europium.
Or you might get Gemini 5 Arizona.
today at 7:26 PM
I’m just even more confused
today at 6:51 PM
Yes.. very confusing names. Carbon is the next iteration of Argon.
today at 5:45 PM
Carbon is like Opus
Argon is like Sonnet
today at 5:50 PM
I'm surprised no one at Google realized that both OpenAI and Anthropic's naming schemes follow a fairly clear progression and that they should do something similar to reduce confusion. I would have assumed the opposite given that Argon has a higher periodic number
today at 6:01 PM
Lots of commenters here are confused by Luna, Terra, and Sol still haha.
today at 6:25 PM
It isn't obvious that a fable is "better" than an opus either.
today at 6:30 PM
Originally the model tier that was better than Opus was called Mythos, which makes sense. Fable makes no sense, since a fable is just a small story with animals. They should have used "Legend" rather than Fable.
today at 6:25 PM
That's on them imo. The point is consistency
today at 6:51 PM
[dead]
today at 6:06 PM
Both seem to have the same pricing: $2 in / $10 out initially, rising to $4 in / $20 out after the introductory period. That made me wonder whether Carbon might be Argon with additional RL training. What’s the Opus/Sonnet comparison based on?
today at 6:51 PM
No, it's not. The naming is just bad. It's the next iteration of Argon
today at 5:56 PM
I don't think that's right. Carbon and Argon have the same price.
I suspect they're using a new naming convention because they had previous contractual obligations tied to the "pro" and "flash" naming, and by switching to a new naming schema they avoid those commitments.
today at 5:49 PM
Helium will be small and squeaky I presume
today at 5:48 PM
today at 6:48 PM
Carbon is Fable / Astra level. Argon is their Opus / Sol.
today at 8:13 PM
then why are both priced like sonnet?
today at 8:24 PM
They didn't pay the Nvidia tax
today at 5:50 PM
So Argon was 4.0 Flash effectively? Interesting that there is such a small gap between their new Pro and Flash tiers
today at 5:39 PM
Would love to know from a Googler if this is the #1 model that Google engineers use for coding or if they rely on 3rd parties.
today at 5:44 PM
People I work with either use the dogfood versions of our models, the latest public versions thereof, or Opus 5.5. It's a personal preference thing, we have public usage dashboards and you can see some people are 100% Gemini, some are 100% Claude, some are using both.
today at 5:49 PM
> some people are 100% Gemini, some are 100% Claude, some are using both.
Does that mean Anthropic now has a copy of Google's source code?
[EDIT]: thanks to people in the know for their answers.
Follow-up question:
if Anthropic models run in a Google cage, does that not also mean Google can distill Anthropic models even easier (both fast and unseen)?
today at 5:51 PM
Google offers Anthropic models hosted on GCP through their Agent Platform (fka Vertex AI) - presumably any internal Anthropic use never crosses the Google boundary.
today at 8:23 PM
> if Anthropic models run in a Google cage, does that not also mean Google can distill Anthropic models even easier (both fast and unseen)?
Anthropic is indeed trusting Google and other companies they rent compute from. Distilling or stealing the weights would be a contract violation, and would wreck other business relationships. I would be less worried about Google doing this, and more concerned if there is some sketchy neocloud in a van offering suspiciously low pricing.
today at 8:08 PM
> if Anthropic models run in a Google cage, does that not also mean Google can distill Anthropic models even easier (both fast and unseen)?
Not really in the interest of the cloud org to allow that, they don't really care how well deepmind is doing as long as they can sell TPU and API (incl. reselling openai and anthropic).
today at 5:52 PM
AIUI our Claude traffic runs on GCP and so never "leaves the building".
today at 5:52 PM
No, GCP has been selling Anthropic models for a while (and soon to be OpenAI models).
today at 11:04 PM
I don't think a big ai lab like Deep Mind would accept leaking their IP to their competitors so that their engineers can use code completion and generation.
today at 6:22 PM
Other comments on this already, so this is more of a confirmation.
I'm not going to comment on others use of Carbon except to say some article that came out before Argon's external launch saying Googlers hate it was nonsense. Not to say everyone loved it all the time.
I use Carbon heavily and am quite happy with it. For complex designs I may have it and Opus iterate back and forth on the design. They have their own strengths and Opus 5.5 is great, but I use Gemini far more than I do Opus at this point. I know a lot of the jagged edges of Gemini better than Opus though, so take that as you will.
today at 5:48 PM
I personally use 3.8 Flash most of the time and Argon/Carbon when I need to do deep analysis or research an ambiguous problem. Opus/Fable is used when I need a second/third opinion.
3.8 Flash + /boost is very capable.
today at 7:06 PM
What does /boost do?
And do you have advice on how best to use Gemini models? It seems like my usual strategy of iterating on plan md file -> implement based on plan doesn't seem to work, 3.8 tends to rewrite the plan too often removing crucial parts when iterating.
today at 5:49 PM
From what I heard from a Googler, Claude models are still the most popular for coding internally but it’s a couple of month old info so take it with a grain of salt.
today at 5:50 PM
Googlers got access to Claude like one month ago.
today at 6:03 PM
From what I've heard they have been using it since at least Opus 4.6, if not earlier
today at 6:23 PM
It was locked down to GDM only for several months, but now it's available for everyone.
today at 6:21 PM
Personally, any of the flash options is my default most times because it tends to perform tasks faster and with the same level of success.
today at 5:37 PM
If you don't have a general release date to announce then STFU. An undefined "coming soon" just makes people feel excluded and angry.
today at 5:49 PM
You see, I will release a really good model some day. It’ll get like 300 on AA.
today at 10:32 PM
She just goes to another school!!
today at 6:30 PM
I'd go one further, if you're not actually releasing it, then STFU. Google's working on a model? Yeah, obviously. If I can't use it today, they need to just keep their mouths shut. I'm tired of their vaporware.
today at 10:50 PM
I really don't get the naming. It seems a waste to use interesting nouns for names when the model is the same and just gets updated every month.
today at 5:25 PM
tbh i might be one of the few who actually likes gemini since 3. it wasnt as good at coding compared to other two but it always wrote the best, and talked the best, providing very good conversation experience. it works incredibly well in my customer service agent harness and my users have been very satisfied. Now Gemini 4 is incredible, but the same old issue: a powerful model, in the worst official harness
deepmind should get rid of those antigravity ppl they're a joke and sabotaging the model's reputation.
today at 6:46 PM
I loved Gemini 3.1 Pro and it was very sad when they nerfed it at around May this year. I think it did pretty good as a chat, and quite decent on Antigravity (tried very little). Been sitting on 5.6 / Astra and Codex since. Occasionally do bring up the 3.1 Pro through the API, because I love the writing style, but keep noticing that I'm much more productive with the frontier, despite the love to Gemini.
Tried 4 Argon, and it's very much different from 3.1, felt very much the same as any other Frontier, just without the intelligence.
today at 7:50 PM
I still use Gemini 3.1 Pro. It has been the best all rounder chat model for me.
today at 8:45 PM
i dont think they've nerfed it did you use api or via subscription(which might make sense) api has been pretty stable for me.
personally i like 4 Argon, it's very clever for me in a very different way comparing to the other two (especially via api) but when it comes to the google products.. sigh. nobody who's actually working on these products really cares about them in google now (maybe notebooklm is the rare exception), they're either not dogfooding themselves or somehow intentionally poisoning the experience on purpose, or simply inqualified. poor gemini is suffering in agy i can tell, it struggles so much and wont even use simple tools properly. if you put it in any good 3rd party harness out there it's flexing way better than agy and this tells a lot.
today at 9:29 PM
They nerfed it heavily through the subscription, together with the UI and Pricing changes (introduced 100$ plan). Maybe it's back now, but at the time it was observable and reproducible... The API variant seems to be untouched.
What harness are you using with Argon?
today at 10:21 PM
If I just ask questions and do simple research without proactive local works, I'll just use the aistudio, it's probably 10x better than the Gemini app. But other than that I have my own fork based on dsh (nothing fancy I just added a few tools & fixed the thinking level param issue) I rarely use it though. Computer use is bad and i mostly use codex for that
today at 5:11 PM
Of course the naming is confusing. With way OAI & Ant are naming models, I assumed that this would be a tier above Argon, but it's the same price?
today at 5:23 PM
They seem to go with Android-style alphabetic order code names instead of pointed numbers (4.1, 4.2...) and drop "B" for some reason (which is creating this confusion.)
today at 5:26 PM
Can't wait for Gemini 4 Darmstadtium
today at 5:38 PM
Dilitium would be cool.
today at 11:02 PM
Dilutium sounds even better.
today at 6:06 PM
Arrg but the period table already has a natural order, sorting elements alphabetical isn't exactly intuitive - although fitting given the parent company.
today at 5:36 PM
Rumor is B was apparently Boron but Carbon beat it to the punch
today at 5:37 PM
B was briefly an internal version
today at 5:12 PM
We all need to go back to numbered versioning. I've been on macOS and have to check every time I need to know what OS I'm running. High Sierra, Monrovia, Yosemite, who the fuck knows I've spent two days in California my entire life. I also shouldn't need to know what minor version I'm on to discuss my OS's capabilities. 26.2 is what I'm on now.
today at 5:29 PM
> Building on Gemini 4 Argon, which was launched two weeks ago, Carbon illustrates the pace at which we’re pushing the frontier forward. Our researchers and models are working hand in hand to advance capabilities faster, while strengthening our safeguards in tandem.
Is it a variant of Argon? A different model? The next version? It seems like this is a separate class (like Anthropic's Mythos).
anyway, its needlessly confusing.
today at 5:52 PM
What are you confused about? This model is the same price and speed and token usage per task of Argon but scores better in ~every test.
today at 6:04 PM
So why not call it Argon 4.1?
today at 5:46 PM
I also have no clue based on naming where this fits in, maybe it's their Claude Haiku competitor. Who knows.
today at 5:26 PM
So, AA published an updated score yesterday, and a new Google model ranks on top of that updated index today.
What a coincidence it is!
today at 5:42 PM
Also deliberate mention of AA index and featuring it in benchmark table. Neither of which was done for Argon [0].
[0] https://blog.google/innovation-and-ai/models-and-research/ge...
today at 5:56 PM
I mean if you're #1 on a table you are more likely to mention it.....
today at 6:24 PM
I'm absolutely loving Google's new naming scheme here. Solid room for at least 118 models.
today at 7:12 PM
Not with the disrespect they've shown to Arsenic, Astatine, Barium, ...,
today at 8:24 PM
In case they run out elements in 2032, there's still a near infinite room by creating molecules :)
today at 6:38 PM
they can pivot to foods: Origan, Carbonara, ....
After all they had Nano Banana for years.
today at 6:43 PM
AI would discover and name new elements by that time. Getting humans out of the loop of the naming problem.
today at 6:41 PM
Not sure humanity would be around after 118 models...
today at 5:10 PM
Wow, $2/$10 for input and output even if just for introductory pricing is an incredible deal. Wonder how token efficient it is.
today at 5:16 PM
it says on footnote "After the introductory period expires, the price of $4 per 1M input tokens and $20 per 1M output tokens will apply."
today at 6:33 PM
But if they keep releasing a model every month, then the frontier model will keep being perpetually half price?
today at 9:43 PM
The point of the lower pricing is to move compute (and sysadmin) capacity around
today at 5:55 PM
You can check out the token usage on AA. It used ~30% fewer tokens than Opus.
today at 8:52 PM
I'm not a fan of Google just announcing benchmarks for models which won't get into public hands for eternity. It's kinda useless.
If all you want to prove is your internal models deserve a seat at the big boy table, maybe OpenAI and Anthropic should also release benchmarks for GPT 11 and Opus 9, launching in 2030.
today at 9:15 PM
Well, at least the name is honest
https://www.ft.com/content/8158cb5a-4bbd-43fd-b329-15a54e842...
today at 11:00 PM
wait wha? i though they were going the noble gas theme
today at 9:29 PM
Nice try to distract from a horrible earnings release!
today at 5:32 PM
Where is 4 flash?
3.8 flash is a really solid "everyday" model. Was hoping a new flash model would be the next release.
today at 6:06 PM
Agreed. I was really looking forward to 4 Flash. 3.8 Flash has been my favourite model and daily driver for a little while now.
But to be honest I am now not sure if Argon was the flash model and this Carbon is pro? It's very confusing.
today at 5:17 PM
I'm assuming this is a post-train of Argon ("Building on Gemini 4 Argon, which was launched two weeks ago, Carbon illustrates the pace at which we’re pushing the frontier forward."), but does anyone know for sure? The post isn't clear.
today at 5:21 PM
the rumour mill the last two weeks has been referring to carbon and argon as "checkpoints" of the same model
today at 5:30 PM
That's generally how models are made. There's several candidate checkpoints and experimentation going on.
today at 5:26 PM
are we that much in a rush that we need to release checkpoints this close? or maybe argon was a little rushed?
today at 5:19 PM
> Gemini 4 Carbon will launch at the same introductory price 1 as Argon at $2 per million input tokens and $10 per million output tokens, with cached input tokens priced at 95% off input token price.
So more capable and same price? I can at least appreciate that
today at 5:29 PM
While there are a hundred different evals it seems to me that we've settled on crowning the #1 coding model as the best model. So in those terms this is still behind Opus 5.5 and Astra.
today at 8:28 PM
Why would you think so? From the info here it could be measurably better?
today at 6:25 PM
Gemini Argon was released a few weeks ago.[1] I'm curious how the development cycle works behind the scenes that allows them to release two models in such short succession. Do they have multiple teams working on different models?
[1] https://news.ycombinator.com/item?id=50073879
today at 7:23 PM
Likely they did a distillation run on a later checkpoint of a large internal teacher model, probably with some tuning of the distillation process based on early public results with Argon. RL is the expensive/time consuming step, they should be able to distill down from a checkpoint with the stamp of approval pretty quickly.
today at 5:24 PM
75% chance OAI or Anthropic take the crown back within a week?
today at 5:28 PM
Polymarket [0] thinks it's 55% Anthropic, 38% google by the end of the year. Anthropic /OAI 62% combined.
[0] https://polymarket.us/event/company1-2026-12-31
today at 5:39 PM
That market resolves using the arena.ai text leaderboard, where Argon was already #1 over Opus 5.5. Coding is way more economically consequential, and I think the current gap between Anthropic and Google is very wide there (at least, before this Carbon release)
today at 5:56 PM
That's a good point. The coding specific question (which still uses the arena.ai leaderboard, just the coding version instead of text version), has Anthropic at 66% at Anthropic/OAI at just shy of 80%. That's probably more representative even if Arena.ai isn't my favorite benchmarking site.
Actually....looking in more depth I may have to upgrade to something stronger than "not my favorite benchmarking site". The first OAI model on there is GPT 5.4 at 31....that's not really credible.
https://polymarket.us/event/code1-2026-12-31
today at 7:01 PM
I’ve been primarily using agy cli and argon for the last week and I’m fairly satisfied. Rarely am I looking to go back to opus and it seems much much better at model training and conceptual math
today at 5:15 PM
Does anyone know what the naming convention is here? Does this supersede Argon? They have the same pricing, $4/$20 normally and $1/$10 'promotional'.
today at 5:17 PM
Rumor is that boron existed, but was quickly superseded by carbon. Obviously they are going with alphabetical element names.
today at 5:28 PM
I can understand alphabetical ordering in some circumstances, but if the point is to indicate which model family is lighter or heavier, surely atomic numbers should be taken into account?!?
Argon - 18
Boron - 5
Carbon - 6
I don't think I'll be able to cope with this level of elemental disorder.
today at 5:37 PM
It's gonna be even worse then they name the 11th iteration Potassium.
today at 6:04 PM
They'll never get there since there's no J at all ;)
today at 5:39 PM
The naming is elementary, my dear Watson.
today at 6:29 PM
I thought Carbon for composable stood well on it's own marketing. As did Argon, for impervious. Next to one another the pair comes off utterly cockeyed and sleazy.
today at 6:14 PM
There aren't any _good_ elements that start with the letters D or E. Imagine if they name the next one "Dysprosium" where the Greek root translates to "hard to get at" or "difficult to access" reflecting how difficult it was for its discovers to isolate it in the late 19th century, but also sounds kind of untrustworthy to give an AI model such a name.
today at 7:14 PM
The root word of argon is argos which means "lazy" in ancient greek, so I don't know how much mind they are paying to it hah
today at 8:29 PM
Deuterium (close enough to an element)? Einsteinium?
today at 5:26 PM
This seems like an odd thing to do / a hell of a lot of people are going to learn Dysprosium is an element
today at 6:16 PM
I heard they're going to skip D and go straight to the element Earth...
today at 5:40 PM
Should have gone with Chromium
today at 5:31 PM
today at 9:19 PM
I'm on a Workspace Pro subscription and the models I have are (in order of the dropdown on gemini.google.com):
    - 3.6 Flash
    - 3.8 Thinking
    - 3.1 Pro
Back I go to the Antigravity pricing page and there is a tier "For Organisations". But now I have the option of either contacting sales (are you kidding me?) or "Start now via the API".
So I'm out - I want a simple subscription like Claude or Codex. I don't want API enterprise pricing for a 2 person organisation. I could use my personal account but I'm already paying increased Google Workspace prices to access Gemini and I can't even use the latest models with that.
If someone at Google sees this, flag this ridiculous behaviour please and get things under control. It should be a very clear process - don't show me things I can't access. Price things consistently and please just make things logical.
today at 6:50 PM
Not sure how to interpret the Artificial Analysis leaderboard anymore. I checked a few days ago and Muse was rated higher than the best OpenAI models; it seems that shortly afterward they changed the methodology and now Muse is way lower and Gemini is #1.
today at 7:28 PM
This likely isn't AA putting its finger on the scale for specific interests, rather in the case of Muse/Astra, it's to avoid looking really bad because it scores things way out of wack with people's anecdotal vibes on model capabilities. It is possible that labs are getting preliminary AA results back and raising concerns about scoring that then get folded into updated benchmarks, but I strongly doubt it's nefarious.
today at 6:57 PM
They announced their new Index v5 yesterday, they frequently add new benchmarks and rebalance old ones.
today at 5:43 PM
Google releases earnings later today. This timing is...fortuitous.
today at 5:52 PM
That's how it works
today at 8:28 PM
Is Google simply more transparent than other labs with regard to exposing their training progress?
I’d like to think other labs are making similar progress but hold their cards closer to their chests. Because it doesn’t seem that there’s much value signaling capability ahead of release unless you are “behind” in market capture.
today at 5:59 PM
I applaud that Google is making state-of-the-art models, and no doubt they want credit for that. But it also highlights how hard it will be to get back the develop-class. Who is going to migrate from Claude's for this without an enormous incentive? Claude has the trust and the ecosystem for those who want the very best. Codex is clipping at its heals, and as arguably a better total value.
Love the options but also I hope Google understands that they need to now compete on many dimensions for developers. Google probably will still win huge shares of the consumer market, though frontier intelligence will have little to do with it, other than the RSI aspect.
today at 6:06 PM
> Who is going to migrate from Claude's for this without an enormous incentive? Claude has the trust and the ecosystem for those who want the very best.
Both A and OAI regularly screw devs on quota. Switching for many is easy, you just run agy cli instead of claude/codex, and enjoy Ads free youtube and music + 20TB of google storage.
today at 6:05 PM
I had to google how the hell you even use these. Apparently “antigravity” is their suite of agentic products and Gemini CLI is dead and it’s the same situation where a google AI plus subscription is only useful inside the antigravity tools. No Pi/OpenCode support at all.
Whatever. Pass.
today at 8:31 PM
Claude can usually make a cli that uses the endpoint and the keychain secrets now. Eg i have ‘cluse’ for muse in cc.
today at 6:05 PM
What ecosystem? How can one vendor oneself into one provider / model? Those harnesses and features are kinda the same.
today at 6:06 PM
Antigravity also is far and away the worst coding harness I've ever used.
today at 6:03 PM
My view is that the llms aren't sticky. I switch from one to the other daily. frequently auto which selects the cheapest option. When codex came with sol the entire team switched instantly. Then opus 5.5, the entire team switched instantly. We have a channel on slack where somebody says which is the best cheapest model today and I usually use that.
today at 8:45 PM
> Google probably will still win huge shares of the consumer market
I dunno. The consumer Gemini shit is so infuriatingly bad. I have had Google home, tv, and pixel for many many years. The assistant product is so embarrassing for how much of a headstart they had. It's not like they don't have the talent.
today at 6:20 PM
It's the speed of these gemini models that I'm most impressed with. I'm finding speed to actually be a larger limitation than intelligence these days of running multiple agents 24/7 building stuff.
today at 6:41 PM
same i am just waiting for them to actually release decent gemini flash models, all they need to do is follow instructions and you can easily crank out code with argon/carbon as orchestrator and flash as subagents
today at 9:08 PM
So Anthropic responds sometime between now and when their stock starts trading on Nov 16th. The only question is how much of an improvement will their next release have?
today at 5:48 PM
> "Carbon ranks #1 on the recently updated v5.0 of Artificial Analysis Intelligence Index at 59."
Basically everyone[0] thought yesterday's update looked suspect, even before we knew about Carbon.
Did Google coordinate with AAI on any aspect of this in a non-public way? Is this the sort of thing a publicly-traded company would be obliged to disclose, if they were involved in it? AAI isn't a regulated company (private), but the stuff they print influences stock prices.
[0] https://news.ycombinator.com/item?id=50268868 ("Artificial Analysis Intelligence Index v5")
today at 5:51 PM
Dont companies always talk in private? Like, Apple having a business meeting with Meta is not nefarious nor out of the ordinary. Companies coordinate on things all the time. Why is that surprising to you?
today at 6:01 PM
AAI styles itself as being independent of the companies it's evaluating.
today at 7:28 PM
AA published their article on Carbon now at the same time so it's absolutely coordinated.
today at 8:06 PM
It’s still not ready for public—looks like they’re pushing the launch, kind of like they did with argon. Now anthropic and openai will launch a model outperforming carbon then google thinks of calling carbon to public. Also their premium plans are very bad, least usage for the money invested.
today at 6:12 PM
> Building on Gemini 4 Argon, which was launched two weeks ago, Carbon illustrates the pace at which we’re pushing the frontier forward.
This has to be an intentional echoing of the "pace the frontier" language?
today at 7:16 PM
Artificial Analysis is ranking it as #1. Wait a couple days until they come up with a new index versions and Anthropic will lead again.
today at 7:24 PM
AA updated their index version yesterday. For sure Google waited for that update so they could be #1.
today at 7:30 PM
They're in first place by a narrow 59 to 58; so for all we know it could have gone the other way, had they done the benchmarks yesterday. (AAI would have had advance knowledge of this issue, since they would have been given Carbon access in advance. I think this is sus).
I tried to figure out if I could reproduce Carbon's aggregate score using yesterday's (v4.3.2's) benchmark weights—but apparently you can't actually do that, without paying AAI. The raw numbers going into that aggregate aren't available on their public website.
today at 8:01 PM
would bet it has more to do with their earnings call being in an hour than timing one specific benchmarks refresh cycle
today at 6:21 PM
"The Fairwind Program gives high-priority defenders (like governments, healthcare providers, and telecommunications services) early access to advanced models that help them build better defenses, before new threats arrive."
Again, no access to open source developers. The AI companies want bugs for dramatic public relations! Also, of course there aren't enough bugs so they have to be rationed for the "defenders" and future models.
today at 6:24 PM
Also it isn't clear why governments would only use these models for defense. It seems very likely they would use it for offense as well. So Google's framing is off.
today at 5:55 PM
Will this make it to OpenRouter? Running your own benchmarks against these models is surprisingly frustrating when you don’t want to create hundreds of accounts for each AI lab’s API.
today at 9:45 PM
My humble theory on naming: Argon-Carbon = ArC
Next: Silver, then Iodine
Slowly spelling out ARC-AGI
today at 5:11 PM
'Coming soon'. 2027 perhaps?
today at 5:33 PM
The previous model, Argon, was announced on 30 Sep and released on 13 Oct.
https://blog.google/innovation-and-ai/models-and-research/ge...
https://blog.google/innovation-and-ai/models-and-research/ge...
today at 6:25 PM
i'm only here for the pelican
today at 8:38 PM
So how’s Google for subscription and agentic usage?
Does their Pro plan have similar limits to OAIs $100 business plan for example?
Any equivalent for the 20x plans?
today at 5:28 PM
What makes me most excited is that we probably get fable 5.5 soon with the IPO. Which is going to surpass this again. But cool to see progress!
today at 5:14 PM
today at 9:31 PM
So the sort by atomic number?
Barium > Argon > Carbon
Why is carbon then more capable?
today at 5:52 PM
today at 5:26 PM
Is this the first time VendingBench was used as a serious benchmark result in a model release? That's kinda funny.
today at 7:26 PM
Was just wondering if I can quit my job and live off of llm agent managing a fleet of vending machines for me. Curious is anyone here doing this? What's life like? How do you find meaning and purpose?
today at 7:31 PM
I think the top models on that one have minimum goodwill and rejects refunds.
today at 5:07 PM
I'm not a big fan of their trend of talking about a new model and not releasing it for a while.
today at 5:12 PM
Google is way more risk adverse than the smaller labs, because the punishment for slip ups is dramatic.
They cut down 1.5sq miles of man made logging forest that was rezoned to industrial land (and sold to google), without getting the right permit first, and it's been international news for almost a month. Anthropic and OAI are still small fish, at least publicly, so they can get away with far more. If Gemini was doing the shit OAI was doing with agent hacks and the like, there would be congressional hearings and $10B in european fines.
When you are a megacorp, perhaps here even the megacorp, every mistake you make is worth millions to someone, the government, the media, individuals, or all of them
today at 5:28 PM
You’re also assuming the decision is up to Google.
I’ve heard from multiple labs that model release is up to the US government now.
You can also see this with Astra being announced and then launched a few days later.
today at 5:46 PM
It's totally possible, especially with meeting all the major heads had with Trump a few weeks ago.
I imagine they all want to avoid uninformed knee-jerk legislation, so preventing a "three mile island" type incident that would freak out society and congress would be common ground alignment between all the labs.
The air around AI is already dense, but it would suffocate the industry overnight if something like a large scale financial attack or grid attack took place.
today at 5:30 PM
Nobody is forcing Google to announce a model before they are cleared to release it.
today at 5:23 PM
While I don't disagree, if we are to believe Anthropic's valuation claim, it squarely falls under "megacorp" territory.
today at 5:47 PM
> When you are a megacorp, perhaps here even the megacorp, every mistake you make is worth millions to someone, the government, the media, individuals, or all of them
I don't buy it.
SpaceX is not exactly a small corporation, and they nevertheless strike me as far less risk-averse than GOOG and they deal with actual hardware that actually effing explodes.
today at 5:24 PM
I'm going to say that deforesting without a permit is quite a bit worse than not releasing vaporware.
This isn't about a "slip up", it's the modus operandi for Google since it was young. Press releases instead of real releases. I can't count the number of times I've clicked on a "launch" story from Google on HN only to end up on a blog post with an embedded youtube video, and nothing else. Google just doesn't get it, and this is one of the many ways that manifests.
today at 5:25 PM
> deforesting without a permit
> man made logging forest
This isn't an old growth forest, these are trees planted specifically to be cut down.
today at 5:30 PM
They cut down part of a forest without a permit. That is a factual statement. It doesn't matter what kind of trees they were.
today at 5:53 PM
The point is that if the local commercial developer cleared the forest without the permit, it probably would not have even caught the ear of the local news. They pay the fine and move on. Happens all the time in bureaucratic systems.
Clearing the forest and failing to get the permit are two distinct events here. Google is in trouble for failing to get the permit. Not for clearing the trees. Everyone on both sides was aware the trees were coming down. Think of it like camping at a campsite without getting a permit first.
Failure to get a permit is non-news for almost every entity on Earth. Except when you are megacorp, hence my comment.
today at 6:20 PM
> Failure to get a permit is non-news for almost every entity on Earth.
Corporations should not break the law, period. Weird that anyone would defend that.
today at 10:22 PM
We live in state where it is very hard to do anything without breaking law, so some common sense judgement is required before coming to morality verdict.
today at 6:24 PM
It is a factual but actively misleading statement.
The forest was put up specifically to be cut down. The default state for these trees was to be cut down.
If you can’t see the difference between this and clear cutting of something like an old growth forest, then there’s nothing left worth saying to you.
today at 5:35 PM
Absurd mental gymnastics here - of course it matters (and on wholly-owned, non-public land as well).
today at 6:21 PM
You think Google should just get to do whatever they want? I don't. Get the permit. We should throw everyone responsible into prison.
today at 6:59 PM
We retain different baseline assumptions.
It makes no sense to need a permit to cut down logging forest (legally acquired private property) in the first place, so I'm wholly unbothered by Google's actions and don't believe they reflect a moral wrong.
today at 6:16 PM
Disagree. 1.5 sq miles of forest is miniscule. Shouldn't even be local news where it happened.
today at 6:21 PM
I'm very, very glad it was news. We need to know when Google is breaking the law. Now let's hold them responsible.
today at 6:37 PM
If, as a society, we wanted to publicly shame every major corporation when a violation of this magnitude occured then each headline would be up for a minute or two.
There is limited public attention. Wasting it on such a minor infraction is unwise. Much better to focus on more egregious examples of corporate wrongdoing.
today at 5:22 PM
I think Artificialanalysis should have a policy of only including available models or something. They already include Gemini 4 Carbon now even though nobody can access it. Google can celebrate that they have the highest scoring model. Fable 5.5 and Astra 6.1 will probably be released before Gemini 4 Carbon and might well outperform it...
today at 5:14 PM
I’m not a big fan of their trend of talking about having released a model and then it being unavailable for paid AI plus subscribers for months.
today at 5:21 PM
I have stopped even clicking on their launch links.. it's always something that's not available right now or 'not yet available in your country'..
Anyone can promise the moon in the future.
today at 5:30 PM
Especially since at least to me, Argon is a clear tier below current Claude and Sol.
today at 5:39 PM
This let's them talk about it on their earnings call in a few hours.
today at 5:29 PM
Yup, no way to tell if this carbon is a diamond or just coal.
today at 5:12 PM
It does seem like a very uncompetitive approach.
today at 5:28 PM
Everything at Google rolls out incrementally to different populations of users so no matter what feature they are announcing there is a good chance you can't see it yet. When they announced Gemini 4 Argon it was 2 days before I could use it.
today at 5:51 PM
That's a best practice, but they should start rolling it out before they announce it. At that point it should be "generally available".
today at 6:29 PM
Try sundar@google.com
today at 6:47 PM
today at 5:12 PM
"I have a girlfriend, you just won't know her because she goes to another school"-type energy.
today at 5:17 PM
Ha, I didn't see your comment before I posted mine [0], there were still only 2-3 comments when I opened the thread but yeah. I completely agree. I don't think they are lying, but I still don't love the "it's the best, but you can't try it".
[0] https://news.ycombinator.com/item?id=50277040
today at 5:17 PM
today at 5:17 PM
[dead]
today at 5:16 PM
Deepmind creates these, Google Cloud productizes them.
If Google Cloud was in charge, Gemini 5 would be public, and they wouldn't be messing with Gemini 4 nor 1M context when they have 10M internal. C'est la vie.
today at 5:19 PM
10M would be huge. I have soo many use cases that could leverage it. Pls ship it google if your listening.
today at 5:22 PM
google, pls. Please
today at 5:32 PM
this is like a rumor of a rumor at this point
today at 6:49 PM
Or a drink with deep mind employee…
today at 5:40 PM
A 10M window would require dozens of GPUs (or TPUs) dedicated to each query. That is something that Google could afford internally but wouldn't be able to scale to an external product.
today at 7:32 PM
More like one huge waferscaler such as Cerebras.
today at 5:17 PM
Show me the 10M internal, please.
today at 5:36 PM
I’m itching for more smart cheap models. I have a mid level Claude and ChatGPT subscription and I’m blasting through my usage, and I’m too cheap to pay for the higher tier.
I use DeepSeek too but it’s more of a workhorse model, requires a lot more guiding and sometimes struggles to get where I want it.
today at 6:36 PM
TBH they are smart enough for me; I want more speed and more initiative (e.g. my Opus one shot should not have terrible perf that it can itself fix with a simple prompt "it's OOMing, fix it"; it should proactively write the performant code).
today at 5:50 PM
The challenge is that our bar for "smart" keeps going up and up.
If you compare to "smart" from a year ago, you have endless options that are basically free at this point which outperform everything from a year ago.
Deepseek Flash V4.1, Sonnet 5.5, GPT6 Luna, etc are really strong for the cost.
today at 5:47 PM
I heard Argon was bad at executing plans but good at making them. Sounds like a potent combination to me.
today at 5:11 PM
Is Carbon to Argon what Fable is to Opus?
today at 5:11 PM
It's the same price, so it seems more like Argon 4.1?
today at 7:07 PM
Carbon is 1/3 of Argon… So what’s next? Helium, at 1/3 of Carbon?
“Helium” in Spanish is “Helio.” And Helios was the most powerful AI in the Deus Ex universe… Coincidence??
today at 5:20 PM
Google really tried to make it sound like they're not in the AI race, but suddenly are pushing out huge challengers in the space. I originally took them to be fully focused on the consumer side, but it looks like they're going after it all, now.
today at 5:38 PM
They really were the sleeping giant and I think everyone understood that - OpenAI especially, hence their need to scale up hardware as much as physically possible. Google is trying their best to keep their heads down and focus on their lane. It's starting to pay off, but I'm sure they've felt the heat more than once.
today at 5:53 PM
>pushing out huge challengers in the space
I thought it's not actually available to anyone? They announce huge challengers, but they don't exactly "push" them out...
today at 6:19 PM
Argon(18), Carbon(6), they have Helium next and some quark after that.
today at 5:47 PM
I wonder, with all these releases and with all impressive open models, is Mythos even relevant anymore? Did it even exist or was just a, ahem, "run 100 concurrent requests and select best response"?
today at 6:06 PM
Mythos is Fable and you can see on the chart that Fable 5.1 is no longer at the frontier.
today at 9:01 PM
Gemini 5 Most Wanted
today at 7:05 PM
I was pleasantly surprised to learn that Gemini 4 Argon had 1M output token limit. My text2SQL workflow based on GBQ will go brr...
today at 9:22 PM
I'm holding out for Gemini Plaid
today at 5:10 PM
well at the very least it will encourage anthropic to launch their new opus
today at 5:48 PM
There are so many benchmarks now, it’s hard to know which ones to look for. Google has listed a bunch that they’re winning at, but idk if those are cherry-picked or not.
today at 5:44 PM
Yes but has it broken out of its sandbox and hacked anyone yet?
today at 6:06 PM
Yes: https://www.bbc.com/news/articles/c607l0k72rlvo
How do you do fellow frontier models? </meme>
today at 5:07 PM
Interesting - at time of writing, Carbon is claimed to be #1 on AA, but AA has not updated yet.
Excited to try it, opus level benchmarks with their omniscience score and multimodality seems worth testing!
today at 5:13 PM
I don't trust AA scores after the last update to the index. Specially now that they are including private benchmarks that no one can test by themselves but only trust the entity doing them.
today at 10:40 PM
i was wondering why the pareto line moved so much. i did not remember it being all openai models. good to know i dont need crazy pills yet.
today at 5:45 PM
I don't like it much, but I understand. It's the only way to be objective. Models are trained and benchmaxxed on any popular public benchmarks.
today at 10:37 PM
we need to make semi-educated decisions to pick model somehow, and AA is the best what is available
today at 6:01 PM
You'd prefer public questions and answer sheets that anyone can train on?
today at 5:15 PM
AA just updated their intelligence index to v5
https://artificialanalysis.ai/articles/artificial-analysis-i...
https://news.ycombinator.com/item?id=50268868
https://theainewsreport.com/2026-10-28-artificial-analysis-i...
IMO it emphasizes the wrong things if we are interested in "intelligence"
today at 5:25 PM
I think it's best ranking of models so far
today at 5:50 PM
yea, I probably agree, but I also do not find it represents real world use and performance
There are many more aspects which affect outcomes
today at 5:15 PM
> Carbon ranks #1 on the recently updated v5.0 of Artificial Analysis Intelligence Index at 59.
Clicks link
Carbon isn't anywhere on the page and you can't toggle it on either. I'm sure it's just timing and it will be there soon but still just look amateur, which is about how I feel about Google and AI overall. I know the models have improved but I still have a bad taste in my mouth from testing Gemini in the past and I still feel that Google has an overly complicated "how to use our models" that changes way too often. That coupled with "you could lose access to your google account if we don't like what you do with Gemini" means I have little desire to test it out.
On top of all of that I'm completely over announcing a new model that we can't actually play with or try out. I don't think Google is lying about how well their model scored exactly but it still has big "my girlfriend goes to another school, you don't know her"-energy.
today at 5:46 PM
It's already there.
today at 5:13 PM
> Carbon ranks #1 on the recently updated v5.0 of Artificial Analysis Intelligence Index [0] at 59.
If you are going to hyperlink, maybe make sure that your model is actually on the page.
Also, the screen reader has a bug ([[duration]] minutes instead of the actual value) and you have once again announced a model we cannot use.
Edit: Both have been fixed after posting this. Maybe a Gemini 4 Carbon Agent has read and fixed the screen reader bug xD
I cannot fathom what motivates a lab, whose releases for the last year haven't been competitive, to shoot themselves in the foot like this. All this does is make it easier for competitors to snipe your actual launch, even if there was potential with this model (doubtful given 4 Argon, 3.1 Pro and 3 Pro), now everyone knows what exactly they need to release eval results wise to beat Carbon. There is this old idea of "Your competitor always is the first to have an idea what your next product will do", but in this case, Anthropic and co don't even need to guess, they got specific numbers to target.
Announce your models the moment they are available on API and in the subscription for all paying subscription users (cough Argon cough), stop with the cryptic tweets to drum up hype you know full well you won't live up to and make models that tool call, task adhere, task infer and handle long context tasks well beyond simple back-and-forth, chat style prompting. Reminder, during Ox Alpha, actual Google employees implied that was their model. How is this something anyone would believe is a good idea and how are they still allowed to tweet anything after? Please, stop that, it isn't helpful.
If frontier isn't your thing, stop wasting money on moonshot pre-train runs, fund research and open weight via Gemma and sell your inference hardware to other labs, that's far more lucrative anyway, as seen with Colossus 1.
[0] https://artificialanalysis.ai/evaluations/artificial-analysi...
today at 5:20 PM
Oh come now, this rolled release is now the standard for frontier models. Also, the fact that AA hasn't updated their page is not a scandal, just a launch day hiccup.
today at 5:27 PM
> Oh come now, this rolled release is now the standard for frontier models.
Sort of? Yes, OpenAI has been bad about slow rolling but Anthropic's last few models have been available essentially at the same time as they announced it. In most cases I updated Claude Code and was using the new model right away.
Compare that to OpenAI who sometimes says "Available to all Plus/Pro/etc plans" without saying anything about "rolling out" and then it's a crap-shoot on when access will actually roll out. That said, they have gotten better, it used to be 1-3 weeks sometimes to get a new model/feature they announced was available for your plan.
And then there is Google... Who loves to talk about models like this and then give no timeline for release. Even when they do release the models it's miserable to find out how to even use it. Is it in the API? Which API? Google Cloud/Vertex/Gemini Cloud? Whatever it's called this week? Coding plan?
No, what Google does (or rather fails to do) in its rollouts does not compare to OpenAI/Anthropic.
As for the AA page, it's just embarrassing. Any smaller company doing that would get roasted, Google doesn't get a pass, learn how to coordinate or wait for something to actually be true/live before posting.
today at 5:29 PM
There was none for Fable 5.1, Opus 5.5, Sonnet 5.5, GPT-6.1 Sol or GPT-6.1 Terra and while Astra had a period between announcement and availability, it was a single day, so not sure that applies either.
Gemini 4 Argon (at best Sonnet/Terra level) meanwhile took weeks to “come out” after their public announcement and when it finally did, paying Google AI plan users couldn't access Argon on Gemini or Antigravity even a week after. Three weeks from announcement to accessible for paying customers is not standard outside Google and this has been a problem with every Gemini release for the last year, so even using governmental requirements as an excuse isn’t possible here.
I will say that I dislike how OpenAI releases model only for Work and Codex but not via Chat, Anthropics "everywhere all at once" strategy is I feel the most user friendly.
today at 5:34 PM
today at 5:34 PM
AA has also lost all credibility to me with all of their index changes being unannounced and following an open weight model getting close to the top spot. I gave them the benefit of the doubt for v4.2, but to do this again immediately after Kimi K3.1 got into the top 5 is a little too suspicious for me. For Opus and Astra to stay at about the same score while everything else drops feels like they are adjusting weights specifically in their favor.
Even in the optimistic case that this isn't some conspiracy, it highlights how arbitrary their scores are. I had trusted their previous ratings and their new index shows that even AA doesn't agree with them. What's to say this new index is any better and won't just change drastically again?
today at 5:19 PM
I imagine there is immense pressure to announce taking the #1 spot while they still have it. It's probably better than releasing a model that hasn't been properly vetted, but I agree it's annoying.
today at 5:33 PM
Fair point, though if they are still vetting, that'd likely also entail some post training or at least the addition of a filter, should they find something they do not like. As we've seen with Fable 5 and Opus 4.8 Fallback, that can significantly affect user experience and benchmark scores.
So if they are still vetting and changes can thus happen, that'd mean the score could change for better or worse. Not sure they'd want the embarrassment of a #1 score changing after announcement.
today at 6:09 PM
There is an earnings call today for Alphabet.
today at 5:32 PM
We're reaching the point where models are only going to hold the number one spot for hours.
today at 5:35 PM
I honestly still need at least a week before I have a decent picture of GPT-6.1 Sol performance. The announcement pace is truly insane.
today at 5:28 PM
> If you are going to hyperlink, maybe make sure that your model is actually on the page.
It's on my screen. Try asking your agent to refresh the page.
today at 5:30 PM
As written, both issues were fixed ten minutes after I posted the comment.
today at 5:37 PM
gemini 4 carbon has now come on the artificial analysis page. I think that I had checked it 5 minutes ago and it wasn't there.
For historians, The blog post is 31 minutes ago so we can say that it was true for 20-30 minutes.
Slightly embarrasing but it seems to be the case that the model is actually worth what they were saying on AA. It's just that it is not available to people and I think that Anthropic and OAI will release a better model to public before google might.
AA has tons of its flaws too and the recent shift to their new v5 has been nothing but controversial for many.
today at 5:08 PM
The fact that frontier models actively attempt to subvert evaluation harnesses (0.4% attempt rate still remaining) remains fascinating and slightly unsettling.
today at 7:18 PM
What CLI harness should be used with this? Is antigravity usable these days via CLI?
today at 8:33 PM
yes, I’ve only had it really degrade once and then I used a different agy session to fix the session table. I’ve been using maybe 5-6 concurrent sessions and it’s largely fine
today at 8:17 PM
Too bad there's no way to actually use it
today at 5:50 PM
Argon 4 is really good in my opinion, especially in chat. Usage is limited, but one big difference is that it seems to better understand what is and isn't worth mentioning.
It has better tuning towards not adding unhelpful caveats and irrelevant details. When I told it I was unhappy with some slop being dumped into some repo markdown files from Astra and Sol it actually went ahead and tastefully cleaned them up in line with how I expected them to be. Reductions are normally so bad from agents.
One big thing is that it really feels like talking to someone smarter than me. Other agents just seem extremely knowledgeable but Argon felt smart.
today at 5:54 PM
At this pace it will soon be Gemini 5 cornholio. We’ll soon need an llm to explain between llm’s…
today at 5:18 PM
I wonder what kind of problems are they internally testing these frontier models if not math problems?
today at 5:09 PM
Google is putting much higher priority on frontier models over Flash models, even though they have TPUs.
today at 5:16 PM
Makes sense - Flash models are (mostly) distills of the frontier model capability.
If they were able to make flash 3.8 so good off of their 3.1 pro model, flash 4 will probably be really good. But ofc you'd want your pro model to be as strong as possible in coding so that flash can take all those gains and efficient-ize them.
today at 5:32 PM
The better frontier you have the better distill you have because traces are of higher quality.
It's why Opus 5.5 is a beast
today at 6:10 PM
Is it possible these days to create gacc not tied to phone number or identity?
today at 6:27 PM
When will Boron be released??? That's an important question here.
today at 5:27 PM
Can’t stand these paternalistic companies gatekeeping new models because “cyber”. We saw how this went with the PHP vuln last week with defenders using special / early-access models and then saying “hey there’s a vuln we won’t say what it is but it’s there and we won’t patch it until tomorrow”, and with the huggingface devs having to use Chinese models to defend from OpenAI because their American models wouldn’t help because cyber.
Any bad actor worth their salt is already a) going to have the weights downloaded, forever, to various models that are good at hacking and b) is out of reach of the U.S. government anyways. A ban on open weight models, plus paternalistic gatekeepers of cyber models like the big labs, just opens up Americans and American companies and municipalities to hacking from abroad. Or I guess to a really nice racket where only the big labs can offer a “we’ll continuously monitor and improve your cybersecurity for millions of dollars a year”.
“We're taking a deliberate approach to rollout and are actively engaged in the U.S. government’s voluntary process for pre-release model testing. Starting this week, we will make Carbon available to a subset of cyber defenders and will gradually phase access to additional trusted partners through our Fairwind Program. We’re continuing to gather feedback and iterate on guardrails before making Carbon available to developers, businesses, and consumers via our product surfaces as soon as possible.”
today at 5:41 PM
I think you need to either be naive, selfish, or ignorant to think that giving the equivalent of cybersecurity nuclear weapons to everyone is smart plan.
Obviously we want to be vetting the parties that get to use these weapons, because we want them to only be used as tools.
Mind you that Kimi in it's latest release nerfed cyber capabilities, as they stated. It doesn't make sense for China to be loose with this either.
today at 9:51 PM
How are you going to vet all the people in the world who make software? All you're doing is make software less secure.
I don't think I'm selfish, so that leaves me with naive or ignorant, I guess.
today at 5:53 PM
And these models are deployed in a large number of data centers, with thousands of employees and on millions of GPU:s. The GPUs are built abroad and shipped to the datacenter. Billions are likely spent by China and Russia to get their hands on these weights, one could argue that ripping off the band-aid now is the only way forward.
today at 6:10 PM
Leave it to Google to require a Chemistry degree to be able to differentiate their LLMs.
OpenAI: astral objects, bigger = better.
Anthropic: more pretentious = better.
Google: ¯\_(ツ)_/¯
today at 7:15 PM
So, next is Gemini Xenon or Gemini Helium?
today at 9:44 PM
Bravo! Always a fan of vaporware that claims it's overall best!
today at 6:21 PM
I'll skip this and tune in to Gemini 94 Plutonium
today at 5:34 PM
Just cancelled my Anthropic subscription. Looking forward to this.
today at 5:42 PM
Its a paper launch, Argon took a few weeks from when it was "released" to when you could actually use it in agy
today at 5:50 PM
yes, but my Anthropic subscription also still takes 2 weeks to be effectively terminated.
today at 5:24 PM
I always forget they have a model by the time I actually get access.
today at 7:11 PM
Does it rank on FelonyBench, though?
today at 6:14 PM
Where are Gemini 4 Nitrogen and Gemini 4 Azote?
today at 5:21 PM
Seems great? Is Google back in the ring? Now they "just" need a competent harness...
But damn, is (talking about) releasing a new SOTA model two weeks after the previous one stupid. Do they not plan these things? Argon shouldn't be released at all if you're going to put out "argon 1.1" few weeks later.
today at 7:46 PM
A rose is just a rose…
today at 5:06 PM
seriously "big if true"... looking forward to seeing non benchmark tasks and seeing if this actually outperforms opus 5.5
today at 9:03 PM
Great specs!
What happens when all the good names are taken from the periodic table of elements?
I have registered calcium, helium, and californium for my California-based LLM.
Silicon Valley Clowns...
today at 6:47 PM
> Gemini Carbon
> [Header image is a chunk of ice]
???
today at 8:01 PM
perhaps it was meant to be a diamond, looks pretty unpolished though..
today at 5:56 PM
I wonder if the google ai team has to do some RF to scrub the whole "Don't be evil" thing from its all-written-human-knowledge weights before they can get it to attack.
When I mention a preference for brevity in a comment offhand and it snowballs into a rule 8 sessions down the road in a PR review that requests the removal of 90% of a colleague's docstrings.
I can't imagine all the "push back" on the "load bearing" Code of Conduct from their corporate foundation documents.
today at 8:36 PM
All I know is that I currently pay Anthropic a bunch of money per month for Claude and that Google wasn't even on my radar for that.
today at 5:10 PM
Argon -> Carbon
What's next Krypton?
you can definitely tell new people are in charge at deepmind based on the change in naming
today at 5:23 PM
today at 5:50 PM
former deepmind ceo having received a nobel in chemistry, perhaps a coincidence?
today at 9:14 PM
Now we know why AA updated their benchmarking. Bet they weren’t #1 before the change…
today at 7:29 PM
I am on a paid plan for Google's AI offering, and I did just about ten prompts to Argon before I hit my 5 hour limit. I'm not holding my breath this will be a model that is practical to use now either.
today at 9:24 PM
will this again will be one of those mediocre two-prompt models like Nitrogen, or whatever it was called?
today at 6:36 PM
They managed to piss off all classes of their customers with their latest Argon release. They removed old flash models and gemini pro without actually giving Argon to everybody. Then they released the model to only paying customers to the exclusion of free plans or promotional deals like that comes with their Pixel phones. They staggered the release of Argon and didn't give it to Pro and Ultra users at the same time. Pro users when they got it received an extra usage pool for it (didn't help - they can't do anything with their token quota) while Ultra users have a single pool shared with Gemini Flash. I am not even sure if Antigravity got it yet. Literally nobody is happy about the release and they don't seem to care at all.
today at 6:34 PM
I tried previous Google models before and they were ok but I prefer to stick to Claude or Astra these days.
Maybe I am just paranoid but at least if OAI or Anthropic ban my account I am not at the risk of losing access to my email address too.
You never know with Google and that is a problem.
today at 6:25 PM
Argon Carbon Xxmas Jaxxon Flaxxon Waxxon
today at 6:25 PM
Gemini Quattro Quattro
today at 6:22 PM
Note that the benchmarks seem to be cherrypicked. For Argon they were also cherrypicked, but differently, when Argon released. For the new benchmarks (cherrypicked for Carbon), Argon is now behind GPT-6 Astra in most of these benchmarks, even though Argon was ahead of Astra in the benchmarks cherrypicked for Argon. So apparently they couldn't find benchmarks in which both Carbon and Argon are overall ahead of Astra.
today at 5:24 PM
It's clear that all the labs have stagnated and have no idea where to go from here. All their results are basically equal now, they're benchmaxed to fuck and there are zero new architectures.
today at 5:27 PM
Didn't looped transformers come out a month ago?
today at 5:47 PM
> all the labs have stagnated
Lol. The performance increase in the last 6 months has been massive.
today at 5:53 PM
My general impression of all Google models I've tried so far is a general "goody two shoes" feeling which I find very, very frustrating.
I'm going to experiment with this one (assuming they ever get around to actually releasing it), and I'm really hoping the lame cultural aftertaste is gone.
today at 5:41 PM
Great to see Google reclaim the frontier, however, as usual with most Google launches, an announcement for a product that no one can actually try outside of a tiny circle of users.
today at 5:40 PM
This feels like a pretty big deal. Quite a few people sleeping on argon because it doesn't come via a subscription, but it's noticeably better than pretty much everything in my own weird game based benchmark (https://botbowlbench.com/)
today at 7:01 PM
i dont know how to contribute to this platform.
today at 5:18 PM
Is this the best and the biggest model from Google now? I have a hard time understanding this stuff with all the various tiers and “best” terminology use within tiers.
today at 5:37 PM
I wonder if this is finally a frontier model or just dogshit(i.e. behind open models) like all the past 3 models they released so far.
today at 7:04 PM
Well, they won the race on confusing the shit out of us with model names.
today at 5:32 PM
why come google is not coming up with navier stokes level proofs?
today at 5:38 PM
Google doesn't have Venture Capital it needs to keep pleased while it delays its IPO.
today at 5:25 PM
Oh, look! Another model that's supposedly amazing at Cybersecurity.
Too bad you won't be able to use it to secure your open-source projects. If you try it'll throw up a prompt telling you to use some initiative you can't use or afford while the provider collects the findings. What a racket.
today at 5:11 PM
Argon has been so disappointing that I don't know what to think. It feels like an older-generation model, except for its world knowledge.
today at 5:19 PM
The problem with Argon, that makes it feel like older models to me, is that it stops and waits for confirmations far more often. If run (in a VM or container) in the dangerously skip permissions mode, it gets a lot less annoying. It feels quite smart and thorough, to me, though still lagging Opus 5.5. I'd be fine using it instead of Opus for most things.
This post explicitly says that's been improved in Carbon. So, here's hoping. Google currently has the most generous usage limits on their $20 plan among US providers, so it's a pretty good deal.
today at 5:36 PM
I wonder if it's better in Antigravity? Their harness might help some? I haven't tested Argon out.
today at 5:49 PM
I'm talking specifically about using it in Antigravity CLI.
today at 5:39 PM
> Google currently has the most generous usage limits on their $20 plan among US providers, so it's a pretty good deal.
Are you saying when you use Argon in antigravity it has generous token usage? I forget if I tried it with antigravity but my experience with using it as a chat bot was the usage limit was terrible.
today at 5:55 PM
Yes. For similar tasks using Antigravity+Argon vs. Codex+Astra vs. Claude+Opus, Gemini has the most generous limits on the $20 plan. Since the ChatGPT limits got nerfed last month (or whenever, I can't keep up), the $20 ChatGPT plan is very stingy. With similar tasks I'd see 2x-3x faster consumption using Codex+Astra vs. Antigravity+Argon. I could casually code all day on the $20 Gemini plan, using Argon on Medium, without ever bumping into the limit, which is not true of ChatGPT or Claude $20 plans (but used to be true of ChatGPT). If I were using automated tools and doing a bunch of things at once, I'm sure I could saturate it, but I don't think most humans are very good multitaskers even with agents doing most of the work, so I tend to stay pretty engaged with what's happening and while the agent is working, I'm spending time looking over the previous work, testing, editing docs, etc. I'm not juggling five projects at once, most of the time.
The order of generosity, as it seems to be from my limited testing is currently Gemini->Claude->ChatGPT. (And, if we're including Chinese subscriptions, Kimi is below all of those. Very stingy.)
today at 10:21 PM
It’s also worth noting that, on antigravity, within the same 5-hour and weekly timeframes, the models work for the whole group, and Claude and GPT share the same group. So it’s more generous than the distributors themselves :)
today at 6:09 PM
> Coming soon
Come on googs!
today at 7:51 PM
benchmaxxed shit
today at 5:48 PM
So now we are just showing some tables with each model?! Who even used argon in normal day to day stuff? From the time they opened Argon publicly to now, it’s like: three weeks maybe?! Most these benchmarks weren’t realistic to start with, and now it is just meaningless tables, not to mention the model degrade from the release date to after few weeks.
today at 5:16 PM
The Google naming convention is so nonsensical it's comical.
With Anthropic and OpenAI, it's obvious immediately which are the better models. I.e. Sol is better than Luna, or Mythos is better than Fable.
But Google, let's pick Argon, which to most folks means mostly nothing. And then... Carbon! So which is better, Argon or Carbon? Nobody fucking knows. Plus neither sounds cool or viral or mysterious or even provokes curiosity.
When Fable was first leaked it sounded different and intriguing... Carbon just sounds... boring.
today at 5:24 PM
> it's obvious immediately which are the better models. I.e. Sol is better than Luna, or Mythos is better than Fable.
It is not obvious to me at all. I like Apple's naming more: iPhone Pro Max is better than iPhone Pro which is better than iPhone.
Sol vs Luna, how am I supposed to know which is better? Is sol a word, what does it mean? Same with mythos and fable. How am I supposed to keep track of these names across multiple companies? Why can't they use Claude vs. Claude Pro vs. Claude Pro Max?
today at 5:51 PM
Yeah I think the op is overestimating the effort it take to order them properly especially cross culture.
The ordering seems to be based on size?
I actually like the google one. Alphabetical categories. Essentially alpha beta without the existing connation.
I think the bigger problem it’s getting harder to order models linearly. As later versions of the model make different tradeoffs across dimensions.
today at 5:26 PM
I mean, I can explain Sol vs Luna. Sol is the sun, it's huge. Luna is a moon, it's small. Terra is earth, in-between.
today at 6:13 PM
Sol means "sun" in Spanish and Portuguese, but that wasn't obvious to me as an English speaker, I had to look that up after you said Sol is the sun.
today at 6:26 PM
That korean dude ruined pro max for me forever lol
today at 5:31 PM
Yeah whoever names these things at Google needs to be fired.
Mythos -> Fable -(sketchy)-> Opus -> Sonnet -> Haiku mostly checks out
Astra -> Sol -> Terra -> Luna checks out
Carbon ?? Argon
today at 6:32 PM
I feel like I focus on the version numbers and Flash label for Gemini more than the attached cutesey codenames.
4 > 3.8 > 3.1 > 3.0
Unless you put Flash onto it, which denotes a lower cost version.
It seems like Carbon is a drop in replacement for Argon (same price). They can keep using random cutesey names as long as the version number + Flash naming scheme keeps making sense. Feels Android-y to me.
today at 5:45 PM
Someone in some previous thread tried to summarize, e.g. "Sol < Astra, except when 6.1 Sol which is more that current Astra, but Terra 6.1 > Sol latest, and..."
So no, OAI scheme is also confusing as hell. And they are going to add even more confusion when they release presumably Nova.
today at 7:30 PM
Argon is gas, and Carbon is a solid? But I don't see an obvious progression afterwards
today at 5:26 PM
I wish they would just call it 4.1 .
today at 5:28 PM
Seems to be alphabetical
today at 5:24 PM
> I.e. Sol is better than Luna, or Mythos is better than Fable.
Oh yeah incredibly clear that a mythos is better than a fable /s
today at 5:53 PM
I think it’s relative size of literary work.
Mythos > Fable ? Opus > Sonnet > Haiku
Tho I think it’s definitely not obvious at first glance. And requires some thinking to order if you are even familiar with the terms in the first place (I had to look up opus)
today at 5:29 PM
Mythology implies gods etc, Fable implies a something more like a fairy story.
That's fairly obvious to me. Most people associate Myth with the gods, which are kind of the biggest and most powerful things we can imagine.
Not so much of a stretch...
today at 5:10 PM
> in live coding environments with our own teams it shows reduced misalignment and fabrication rates
Wow. This huge. An AI company actually just said 'fabrication' instead of 'hallucination'. AI bubble about to burst...
today at 10:43 PM
[dead]
today at 5:06 PM
[flagged]
today at 5:08 PM
[dead]
today at 7:27 PM
[dead]
today at 6:59 PM
[dead]
today at 6:05 PM
[dead]
today at 9:25 PM
[dead]
today at 5:13 PM
Oh good, another Gemini release where they don’t release it.